Skip to content
Artwork for Ship It Weekly - DevOps, SRE, Platform and Cloud Engineering News
NewsTech NewsTechnology

Ship It Weekly - DevOps, SRE, Platform and Cloud Engineering News

Teller's Tech - DevOps, SRE and Cloud Podcast

Ship It Weekly is a short, practical recap of what actually matters in DevOps, SRE, cloud infrastructure, and platform engineering.

Each episode, your host Brian Teller walks through the latest outages, releases, tools, and incident writeups, then translates them into “here’s what this means for your systems” instead of just reading headlines. Expect a couple of main stories with context, a quick hit of tools or releases worth bookmarking, and the occasional segment on on-call, burnout, or team culture.

This isn’t a certification prep show or a lab walkthrough. It’s aimed at people who are already working in the space and want to stay sharp without scrolling status pages, cloud updates, and blogs all week. You’ll hear about things like cloud provider incidents, Kubernetes and platform trends, Terraform and infrastructure changes, and real postmortems that are actually worth your time.

Most episodes are 15–30 minutes, so you can catch up on the way to work or between meetings. Every now and then there will be a “special” focused on a big outage or a specific theme, but the default format is simple: what happened, why it matters, and what you might want to do about it in your own environment.

If you’re the person people DM when something is broken in prod, or you’re building the cloud and platform everyone else ships on top of, Ship It Weekly is meant to be in your rotation.

Play
  • 31 episodes
  • weekly
  • Avg 25 min
  • English
Counted on this page — what you have heard stays on this device, so it is not something the list can be paged by.
  • #73
    Monday · 45 min

    Ship It Conversations: Rob Koch of Slalom on Accessible Cloud Native, Sign Language Recognition with Kubeflow, Overhyped AI, Conference Accessibility, and Why Teams Should Hire Deaf Engineers

    This is a guest conversation episode of Ship It Weekly, separate from the weekly news recaps. In this Ship It Conversations episode, I talk with Rob Koch about what accessible cloud native actually looks like, why sign language is still one of the hardest problems in AI, and why the fastest way to make your tooling accessible is to hire deaf engineers. Rob is a senior principal at Slalom, an AWS Hero, and co-chair of the CNCF Deaf and Hard of Hearing Working Group. Rob is Deaf, and his ASL interpreter, Amelia Fruehsamer, voices his answers. Special thanks to Amelia for interpreting the conversation. We start with an analogy Rob comes back to all episode: cloud native is the toolbox, and platform engineering is the workbench. Then we get into what's overhyped about AI, the guardrails it still needs, and what auditable AI observability looks like. A big part of the conversation is accessibility in practice. Rob explains how captions pushed for deaf attendees ended up helping neurodivergent folks too, and what conferences get wrong: accessibility planned at the very end instead of the start, and the real cost of interpreters versus captions. Then we get technical. Rob walks through using Kubernetes and Kubeflow to train models that recognize sign language, and why it's so hard: regional signs, lighting, skin tone and backgrounds, and a camera that can't tell which way a hand is facing. His joke: we don't have AGI until AI understands sign language. The big takeaway: start with people, not a checklist. Hire deaf and hard of hearing engineers, ask them how they want to work, and your tools get more accessible because they're in the room. Highlights • Cloud native as the toolbox, platform engineering as the workbench • What's overhyped about AI, and the guardrails it still needs • What accessible cloud native means in practice • Captions that help far more people than you planned for • What conferences get wrong about accessibility, and what it costs • Kubernetes and Kubeflow for sign language recognition • Gesture-based computing and why speech-to-text had a 30-year head start • Where to start: hire deaf engineers Links Rob Koch on LinkedIn: https://tsn.io/4qmFo Rob Koch on GitHub: https://tsn.io/Mbxrs Amelia Fruehsamer (Rob's ASL interpreter) on LinkedIn: https://tsn.io/UJB88 CNCF Deaf and Hard of Hearing Working Group: https://tsn.io/tB1lS CNCF conference accessibility best practices: https://tsn.io/BZvpv CNCF Merge Forward: https://tsn.io/QPVNQ Kubeflow: https://tsn.io/4OVKf More episodes and show notes: https://tsn.io/NqkdP On Call Brief: https://tsn.io/Gpz2d LMGT Awards: https://tsn.io/lAERA

    • Transcript
  • #72
    Saturday · 14 min

    GitHub Actions Lockfiles, GitLab CVSS 10 CI Flaw, Google Cloud Storage Outage & Torvalds Builds Kernel Patches With Claude Code

    This week on Ship It Weekly, GitHub Actions workflow lockfiles land in public preview, pinning actions and their dependencies to exact commits. GitLab shipped a critical patch release for CVE-2026-97229, a CVSS 10 CI/CD regex flaw that could let an unauthenticated attacker run code on the server. Google published its final report on two Cloud Storage incidents in us-central1, including a recurrence caused by an incomplete rollback. And Linus Torvalds pushed an experimental kernel branch with page-cache patches built using Claude Code, as maintainers debate dropping the mandatory AI attribution tag. The thread this week: know what you're actually running, from the commit you reviewed to the state a rollback really left behind and code someone can still explain. In the lightning round: a record Patch Tuesday with more than 1,400 CVEs and an actively exploited Windows Shell bypass, GitHub AI Scan for pull requests and agentic autofix going GA, AWS Strands Box, an open-source agent sandbox that keeps real credentials out of the agent's environment, and a Microsoft 365 outage through Global Secure Access. The human closer comes from Paul LaPosta's “Your error budgets don't know AI exists.” AI has split shipping a change from understanding it, and SLOs don't measure comprehension. Your SLO can tell you the service is up. It cannot tell you whether anyone still understands it. Programming note: Ship It Weekly turns one next month, so expect more conversations over the next couple of months, usually two a week, starting Monday with Rob Koch. Links GitHub Actions workflow lockfiles GitLab 19.4.2 / 19.3.5 / 19.2.8 patch release Google Cloud Storage incident report Linus Torvalds and Claude Code (Phoronix) Linux drops the Assisted-by requirement (Phoronix) October 2026 Patch Tuesday GitHub AI Scan for pull requests GA Agentic autofix GA AWS Strands Box Microsoft 365 Global Secure Access outage Your error budgets don't know AI exists (LeadDev) This week's On Call Brief

    • Transcript
  • #71
    October 12 · 39 min

    Ship It Conversations: Erik Osterman of Cloud Posse on Terraform Modules, IaC Frameworks, Atmos, Internal Developer Platforms, AI Agents, and Why Conventions Matter More Than Ever

    This is a guest conversation episode of Ship It Weekly, separate from the weekly news recaps. In this Ship It Conversations episode, I talk with Erik Osterman of Cloud Posse about Terraform modules, infrastructure as code frameworks, internal developer platforms, and why AI makes conventions more valuable, not less. Erik is the founder and CEO of Cloud Posse, which has published more than 180 open source Terraform modules, and he hosts Cloud Posse's weekly DevOps Office Hours. We start with what AI has done to open source infrastructure projects, then get into what makes a good Terraform module: consistent naming, a consistent interface, not so small that it wraps a single resource, and not so large that it has a hundred inputs nobody can test. We also talk about CloudFormation, Pulumi, and why HCL's constraints helped build the module ecosystem. Erik explains where Crossplane fits, and why accounts, IAM, networking, DNS and certificates all come before the cluster. A big part of the conversation is frameworks. Erik argues that nobody actually runs "vanilla Terraform," because Terraform alone doesn't handle state layout, promotion, authentication, tool installation or repository structure. Every team ends up building its own framework, usually undocumented. We talk about Terragrunt, Atmos, naming conventions, brownfield adoption, and breaking a monolithic root module into services. Near the end, we get into AI and self-service. Erik's team now generates most of its infrastructure work with AI, and it works because the conventions, agent skills, MCPs and pipelines are already in place. Self-service doesn't have to mean another no-code platform. The big takeaway: AI can generate infrastructure code faster than ever, but without conventions it is generating into chaos. Highlights • What makes a good Terraform module • Root modules vs. child modules • CloudFormation, Terraform, Pulumi, and why constraints helped HCL win • Where Crossplane fits, and what has to exist before the cluster • Why internal developer platforms like Backstage come after zero-to-one • Why infrastructure as code needs frameworks, not just modules • Agent skills, MCPs, and self-service without a no-code platform Links Cloud Posse: https://cloudposse.com Atmos: https://atmos.tools Cloud Posse on GitHub: https://github.com/cloudposse DevOps Office Hours: https://tsn.io/2gq7v Erik Osterman on LinkedIn: https://www.linkedin.com/in/osterman More episodes and show notes: https://tsn.io/NqkdP On Call Brief: https://tsn.io/Gpz2d LMGT Awards: https://lmgt.org

    • Transcript
  • #70
    October 10 · 17 min

    Critical Atlassian CVE Hits Jira, Confluence & Bitbucket, GitHub Copilot Sandboxing Goes GA, AWS Lambda SnapStart for Containers & Google Spanner Omni

    This week on Ship It Weekly: Atlassian disclosed a critical arbitrary file access vulnerability affecting eight Data Center products, including Jira, Confluence, Bitbucket, and Bamboo. GitHub Copilot local sandboxing is now generally available, giving teams enforceable controls around filesystem, network, credentials, and local tooling. AWS published a deeper look at Lambda SnapStart for container images, including the operational risks of restoring initialized state. And Google Spanner Omni is now generally available, bringing Spanner outside Google Cloud and putting more of the availability responsibility back on the customer. The bigger theme this week is control. Developer tools are production infrastructure. AI agents need real execution boundaries, not just instructions. Faster startup through snapshots means understanding exactly what state is being restored. And moving a managed database onto your own infrastructure gives you portability, but also gives you the pager. In the lightning round: Citrix has a NetScaler SAML vulnerability under active exploitation. Cloudflare is working toward becoming a publicly trusted certificate authority. And attackers are actively scanning for Rejetto HFS servers vulnerable to a flaw that can lead to account takeover and remote code execution. And the human closer comes from Lorin Hochstein and a recent Google Cloud networking incident. One part of the outage involved someone correctly following an incorrect procedure, while another involved someone incorrectly following a correct one. Training matters, but systems also need guardrails that keep normal human mistakes from turning into large outages. If your system only works when nobody makes a mistake, the system is the problem. Links Atlassian CVE-2026-21589 https://tsn.io/ZlqKv GitHub Copilot Local Sandboxing https://tsn.io/rQngM AWS Lambda SnapStart for Container Images https://tsn.io/uXqkK Google Spanner Omni GA https://tsn.io/GoZZ5 Citrix NetScaler CVE-2026-88779 https://tsn.io/yN5a9 Cloudflare Certificate Authority https://tsn.io/egMN5 Rejetto HFS CVE-2026-61500 https://tsn.io/oQrkU Google Cloud Networking Incident https://www.tellerstech.com/go/s-dc989ad2/ There Was a Light That Never Went Out https://www.tellerstech.com/go/s-cb0bc459/ This Week’s On Call Brief https://tsn.io/8yaIY Ship It Weekly https://tsn.io/NqkdP On Call Brief https://tsn.io/Gpz2d

    • Transcript
  • #69
    October 1 · 16 min

    AWS Retires DevOps Guru: What the End of Support Means, Kubernetes Cross-Namespace CVE-2026-2270, Node.js Undici WebSocket DoS & Cloudflare’s New CLI for AI Agents

    This week on Ship It Weekly: AWS is retiring Amazon DevOps Guru and pointing customers toward CloudWatch and the newer Amazon DevOps Agent. Kubernetes disclosed a vulnerability where StatefulSet and ControllerRevision permissions can allow cross-namespace pod creation under specific conditions. A vulnerability in Undici can let a malicious WebSocket server crash a Node.js process through compressed data. And Cloudflare launched a new CLI as AI agents grow from 25 percent to 48 percent of Wrangler usage. The bigger theme this week is how the systems around our infrastructure are changing. Managed cloud services still have lifecycles that eventually become migration work. Kubernetes authorization can depend on what controllers do with the resources users are allowed to manipulate. Applications acting as clients still process untrusted data. And infrastructure tooling is starting to treat AI agents as first-class users rather than humans who happen to automate commands. In the lightning round: another Kubernetes vulnerability affecting Windows nodes can expose NetNTLMv2 credentials through NTLM coercion. GitHub now supports custom runners for Dependabot version and security updates. And external systems like a CMDB or internal developer portal can push repository properties into GitHub while remaining the source of truth. And the human closer comes from Lorin Hochstein and SRE Weekly. Some availability risks are probably never going away. Resources are finite, networks fail, security controls can affect availability, and production systems have to change. Preventing individual failures still matters, but incident response is part of reliability engineering too. Sometimes improving reliability means getting better at handling the failures you cannot eliminate. Links Amazon DevOps Guru End of Support - https://tsn.io/GQHN8 Kubernetes CVE-2026-2270: Cross-Namespace Pod Creation - https://tsn.io/BsNs8 Undici CVE-2026-85024: WebSocket Denial of Service - https://tsn.io/LncLd Cloudflare: Introducing the cf CLI - https://tsn.io/Wk3ma Cloudflare Forge - https://tsn.io/bAPJu Lightning Round Kubernetes CVE-2026-76654: Windows NTLM Coercion - https://tsn.io/36Kc3 GitHub: Custom Runners for Dependabot - https://tsn.io/tYl9K GitHub: External Custom Properties - https://www.tellerstech.com/go/s-1fd1396d/ Human Closer Omnipresent Availability Risks in Cloud Software - https://www.tellerstech.com/go/s-076db9dd/ Our Links This Week’s On Call Brief - https://tsn.io/fKB9V Ship It Weekly - https://tsn.io/NqkdP On Call Brief - https://tsn.io/Gpz2d

    • Transcript
  • #68
    September 25 · 17 min

    AWS Puts Elastic Beanstalk on EKS, CrowdSec Supply-Chain Breach, Critical Next.js RCE, Microsoft Disrupts EvilTokens & Why Fixing the Initial Compromise Isn’t Enough

    This week on Ship It Weekly: AWS introduced Elastic Beanstalk Cluster Mode, allowing multiple applications to run on shared EKS infrastructure while AWS handles much of the Kubernetes complexity. CrowdSec published how a software supply-chain compromise led to attackers copying roughly 170 private repositories using a stolen OAuth token. A critical Next.js vulnerability in ImageResponse can lead to remote code execution through attacker-controlled SVG data. And Microsoft disrupted EvilTokens, a cybercrime platform linked to more than 12,000 compromised inboxes across 10,000 organizations. The bigger theme this week is what happens after trust has been established. Elastic Beanstalk Cluster Mode puts more infrastructure behind a managed abstraction, but shared infrastructure still means understanding isolation and blast radius. CrowdSec shows how an initial compromise can become a credential problem long after the malicious code is gone. Next.js shows how something as ordinary as generating a social preview image can expose a server-side execution path. And EvilTokens shows how attackers can use valid access to move faster once inside an account. In the lightning round: F5 has a critical BIG-IP APM vulnerability under active exploitation. GitHub Enterprise Cloud can now export an inventory of credentials with enterprise access, including PATs, SSH keys, OAuth tokens, and GitHub App credentials. Zyxel patched a vulnerability affecting GS1900 switches. And Veeam Agent for Microsoft Windows has a privilege-escalation vulnerability that can lead to SYSTEM access. And the human closer comes back to CrowdSec. Removing the malicious package, patching the server, or reimaging the workstation does not necessarily end the incident. If an attacker already stole an OAuth token, cloud credential, SSH key, session, or registry credential, that access can survive long after the original compromise is gone. Containment means understanding not only how the attacker got in, but what they took with them Links AWS Elastic Beanstalk Cluster Mode https://tsn.io/1xaV7 CrowdSec Supply-Chain Attack Analysis https://tsn.io/7yq2f Next.js ImageResponse Security Advisory https://tsn.io/8JvHp Microsoft: Disrupting EvilTokens https://tsn.io/DtbC9 Microsoft: EvilTokens and Device-Code Phishing https://tsn.io/ZzwtD F5 BIG-IP APM CVE-2026-94127 https://tsn.io/sFuKW GitHub Enterprise Credential Inventory https://tsn.io/7bpMn Zyxel GS1900 Security Advisory https://www.tellerstech.com/go/s-b2595852/ Veeam Agent for Microsoft Windows Vulnerability https://www.tellerstech.com/go/s-166d3119/ This Week’s On Call Brief https://tsn.io/Nnd8g Ship It Weekly https://tsn.io/NqkdP On Call Brief https://tsn.io/Gpz2d

    • Transcript
  • #67
    September 19 · 15 min

    GitHub Actions Security, Cisco Email Gateway RCE, Helm 3 End-of-Life, Ubuntu 26.04 Runners & Why “Nothing Changed” Is Never the Whole Story

    This week on Ship It Weekly: GitHub Actions workflow execution protections are now generally available, giving organizations more control over who and what can trigger individual workflows. Cisco is patching critical vulnerabilities in Secure Email Gateway, including an actively exploited issue that can lead to remote command execution as root. Helm 3 has reached its final minor release and is heading toward end-of-life in February 2027. And GitHub’s ubuntu-latest Actions runner is preparing to move from Ubuntu 24.04 to 26.04. The bigger theme this week is infrastructure that changes even when your code does not. GitHub is making CI execution permissions more explicit, Helm teams now have a defined migration deadline, and the ubuntu-latest transition is a good example of how a completely unchanged workflow can suddenly be running in a different environment. Pinning everything forever is not necessarily the answer. The important part is knowing which dependencies are allowed to move and testing those changes deliberately. In the lightning round: GitHub Actions checks, workflow runs, and statuses will begin following your configured retention period on October 1. GitHub Advanced Security can now enforce configurations from the enterprise level. GitHub added API support for tracking when self-hosted Actions runner versions lose support. And AI Scan for pull requests can now be used without requiring CodeQL default setup. And the human closer starts with a sentence almost every infrastructure engineer has heard during an incident: “But nothing changed.” Maybe nothing changed in the application, but the runner image changed, a dependency moved, a certificate expired, DNS changed, or an external service behaved differently. Latest tags, loose version constraints, external APIs, and even support windows are dependencies. The goal is not to freeze everything forever. It is to avoid accidental mutability, where something can change without the team realizing it was ever allowed to change. Links GitHub Actions Workflow Execution Protections https://tsn.io/fbqif Cisco Secure Email Gateway Security Advisory https://tsn.io/jX2wk Helm 3 End of Life https://tsn.io/Ii7jb Ubuntu 26.04 GitHub Actions Runners and ubuntu-latest Migration https://tsn.io/7IJ9k GitHub Actions Retention Changes https://tsn.io/idFxy GitHub Advanced Security Configuration Enforcement https://tsn.io/8vRMx GitHub Actions Self-Hosted Runner Lifecycle API https://tsn.io/9UhY1 GitHub Code Scanning AI Scan https://tsn.io/ULAVW This Week’s On Call Brief https://www.tellerstech.com/go/26w38/ Ship It Weekly https://tsn.io/NqkdP On Call Brief https://tsn.io/Gpz2d

    • Transcript
  • #66
    September 12 · 14 min

    Amazon Linux 2027, GitHub Actions Cache Security, Secret-Scanning Merge Blocks, N-central CVSS 10 RCE, Karmada Graduation, ShieldCrash, CodeQL ARM64 & When Observability Fails Too

    This week on Ship It Weekly: Amazon Linux 2027 enters public preview with kernel 7.1+, SELinux enforcing by default, DNF5, newer language runtimes, AWS-LC, and an x86-64-v3 baseline. GitHub Actions adds explicit cache permissions to reduce cache-poisoning risk. GitHub can now block pull requests from merging when they introduce exposed secrets. And N-able N-central has a critical pre-auth RCE that Huntress says is being actively exploited in the wild. The bigger theme this week is catching problems before they turn into incidents. Amazon Linux 2027 gives teams time to test AMIs, bootstrap scripts, agents, Terraform, CloudFormation, and CI/CD before the next platform generation becomes production reality. GitHub’s new cache controls make workflow trust boundaries explicit instead of leaving them implied. And secret-scanning rulesets move credential detection directly into the merge path, where developers can actually act on it. In the lightning round: Karmada graduates from the CNCF as multi-cluster and distributed AI scheduling grow, ShieldCrash research claims another Microsoft Defender patch bypass with SYSTEM-level access, CodeQL 2.27 adds native Linux ARM64 support, and Dependabot can now read private GitHub Packages without another personal access token. And the human closer is about what happens when observability shares the same failure domain as the thing it is watching. A full disk is bad enough. It gets worse when logs stop writing, monitoring data disappears, and the tools used to diagnose the outage start failing too. The takeaway is not that every monitoring component needs total isolation. It is that you should know what can blind you, and make sure at least one useful signal survives the failures you care about most. Links Amazon Linux 2027 Public Preview https://tsn.io/NHlEa Amazon Linux 2027 Overview and Preview Details https://tsn.io/izDYx Amazon Linux 2027 Known Issues and Preview Limitations https://tsn.io/tdugd GitHub Actions Cache Permissions with cache-mode https://tsn.io/8p94n Block Pull Requests with Exposed Secrets from Merging https://tsn.io/BspA2 N-able N-central 2026.3 Hotfix 4 https://tsn.io/xredG Huntress: N-able N-central Vulnerability and Active Exploitation https://tsn.io/QjNd5 Karmada Graduates from the CNCF https://tsn.io/lcJGh Microsoft Defender ShieldCrash Zero-Day Research https://tsn.io/YfsJ6 CodeQL 2.27 Adds Linux ARM64 Support https://tsn.io/lxfnF Automatic Dependabot Access to GitHub-Hosted Registries https://tsn.io/pSilA Ship It Weekly https://www.tellerstech.com/go/siw/ On Call Brief https://www.tellerstech.com/go/ocb/

    • Transcript
  • #65
    September 4 · 17 min

    AWS GWLB TCP Reset, Azure DevOps Live Migrations to GitHub, GitHub Runner Enforcement, Docker Root Risk, Lambda IAM Updates, PostgreSQL Upgrade Traps, SonicWall Zero-Days & Better Incident Reviews

    This week on Ship It Weekly: AWS Gateway Load Balancer gets TCP Reset, giving applications a faster way to recover when firewalls or other inline appliances fail instead of waiting minutes for TCP retries to time out. Microsoft puts Enterprise Live Migrations into public preview for moving Azure DevOps repositories to GitHub Enterprise Cloud with data residency while developers keep working. GitHub is beginning enforcement against outdated self-hosted Actions runners. And Omarchy fixes a Docker configuration that effectively gave normal desktop processes a path to root. The bigger theme this week is failure modes hiding inside infrastructure we already trust. A dead network path can look like a slow application. A repository migration involves far more than copying Git history. A self-hosted runner can quietly become unsupported while it continues looking healthy. And giving a developer access to the Docker socket may sound like convenience until you remember that the Docker group is effectively a root-level privilege. In the lightning round: Lambda gets full IAM resource-based policies, AWS warns that circular PostgreSQL role memberships can stall major RDS and Aurora upgrades, a researcher releases the FalconFlank CrowdStrike privilege-escalation PoC while CrowdStrike investigates, and SonicWall patches two SMA1000 zero-days after confirming active exploitation. Links AWS Gateway Load Balancer TCP Reset https://www.tellerstech.com/go/s-d7e609ab/ Azure DevOps Enterprise Live Migrations Public Preview https://www.tellerstech.com/go/s-ea05aff9/ GitHub Actions Self-Hosted Runner Minimum Version Enforcement https://www.tellerstech.com/go/s-6e8540c4/ Omarchy: Any User Process Can Escalate to Root https://www.tellerstech.com/go/s-d22971c3/ AWS Lambda Full IAM Resource-Based Policies https://www.tellerstech.com/go/s-ff2a04b5/ Fix Circular Role Dependencies Before Upgrading RDS and Aurora PostgreSQL https://www.tellerstech.com/go/s-e4578f52/ FalconFlank CrowdStrike Privilege Escalation PoC https://www.tellerstech.com/go/s-8c21b00b/ SonicWall SMA1000 Zero-Day Advisory https://www.tellerstech.com/go/s-559ffc8b/ Remote Incident Reviews: Async First, Live Later? https://www.tellerstech.com/go/s-68ca9f5e/ This Week’s On Call Brief https://tsn.io/L95NS Ship It Weekly https://www.tellerstech.com/go/siw/ On Call Brief https://www.tellerstech.com/go/ocb/

    • Transcript
  • #64
    August 29 · 16 min

    Cloudflare Saves 100TB of RAM, AI Drives Server Prices Up, AWS Adds a Fourth London AZ, Route 53 DNS Self-Service, AKS eBPF Routing, Go 1.27, and the Danger of Hidden Infrastructure Assumptions

    This week on Ship It Weekly: Cloudflare explains how five low-level optimizations to the cache behind 1.1.1.1 freed roughly 100 terabytes of RAM while also improving performance. OVHcloud is raising infrastructure prices as AI demand reshapes the memory supply chain. AWS adds a fourth Availability Zone to London, exposing automation that quietly assumed there would always be three. And Route 53 Global Resolver gets a cleaner cross-account model for DNS self-service. The bigger theme this week is assumptions. A few wasted bytes do not matter until you have 250 billion cache entries. A Region having three Availability Zones feels permanent until AWS adds a fourth. And centralized DNS governance works fine until every application team needs a networking ticket just to make a private zone resolvable. In the lightning round: new research looks at manipulating DRAM controller translation registers and the assumptions that creates for memory isolation, AKS eBPF Host Routing reaches general availability, CloudFront Functions can now put custom context directly into access logs, and Go 1.27 lands generic methods along with runtime, tooling, and standard-library improvements. And the human closer looks at an easy Kubernetes mistake: running kubectl against the wrong cluster. Because the active context belongs to the kubeconfig rather than a terminal tab, changing it in one shell can silently affect another. It is a good reminder that some friction is worth keeping around production, and that the safest guardrails live somewhere stronger than operator memory. Links Cloudflare: How We Saved 100 Terabytes of Memory by Optimizing 1.1.1.1’s DNS Cache https://www.tellerstech.com/go/s-9d6c2943/ OVHcloud Raises Prices as AI Memory Demand Reprices Non-AI Infrastructure https://tsn.io/tnaYj AWS Adds a Fourth Availability Zone to Europe (London) https://tsn.io/YfGxa Shared DNS Views with Amazon Route 53 Global Resolver https://tsn.io/WEyig DRAM Controller Register Manipulation Breaks CPU Memory Isolation https://tsn.io/QKr1x AKS eBPF Host Routing https://tsn.io/T3PMh CloudFront Functions Unified Logging https://tsn.io/nTXLn Go 1.27 https://tsn.io/vfXIT kubectl Ran on the Wrong Cluster? Fix Your Context Switching https://tsn.io/6LxfG This Week’s On Call Brief https://tsn.io/064QE Ship It Weekly https://www.tellerstech.com/go/siw/ On Call Brief https://www.tellerstech.com/go/ocb/

    • Transcript
  • #63
    August 24 · 41 min

    Ship It Conversations: Justin Garrison of Sidero Labs on Kubernetes, Platform Engineering, AI, Golden Paths, and Knowing What to Say No To

    This is a guest conversation episode of Ship It Weekly, separate from the weekly news recaps. In this Ship It Conversations episode, I talk with Justin Garrison of Sidero Labs about Kubernetes, platform engineering, bare metal, AI, golden paths, and why knowing what to say no to may be one of the most important skills a platform team can develop. Justin is Field CTO at Sidero Labs, the company behind Talos Linux, and co-host of Fork Around and Find Out. We start with the evolution of Kubernetes and how managed services like EKS and GKE made Kubernetes easier to consume while also pulling teams deeper into proprietary cloud ecosystems. Justin explains why on-prem and bare metal are getting renewed attention, especially as teams look at cloud costs, data sovereignty, and the operational overhead that comes with constantly optimizing cloud environments. We also get into where Kubernetes helps and where it becomes self-inflicted pain. Justin talks about abstraction, cognitive load, and why teams tend to use familiar tools for problems they were never really designed to solve. A big part of the conversation is platform engineering and golden paths. Justin argues that every organization needs its own path, but platforms become dangerous when they try to centralize everything. He shares why one of the best decisions his team made at Disney Plus was simply saying no to stateful workloads. We also talk about what really belongs in a platform: security controls, logging, monitoring, software supply chain visibility, and cost management. Justin explains why centralization can help in those areas, but can become a bottleneck when applied too broadly. Near the end, we get into AI, security, tooling dependency, and engineering culture. Justin makes the point that people have always formed strong attachments to tools, and AI is another version of that. The challenge is knowing where AI actually helps versus where it becomes another dependency teams stop questioning. The big takeaway: good platform engineering is not about supporting everything. It is about understanding what should be standardized, what should stay flexible, and what your team should explicitly refuse to own. Highlights • Why Kubernetes has become increasingly productized • Why some teams are moving back toward on-prem and bare metal • Where cloud cost optimization starts to become its own operational burden • Why Kubernetes helps with abstraction and cognitive load • Why familiar tools often get used for the wrong workloads • What golden paths actually represent inside an organization • Why platform teams need to know what to say no to • What should and should not be centralized • How AI changes engineering workflows without changing the need for judgment • Why finding work you actually enjoy matters for avoiding burnout Links Sidero Labs: https://www.siderolabs.com Talos Linux: https://www.talos.dev Justin Garrison: https://justingarrison.com Fork Around and Find Out: https://www.forkaroundandfindout.com More episodes and show notes: https://shipitweekly.fm On Call Brief: https://oncallbrief.com LMGT Awards: https://lmgt.org

    • Transcript
  • #62
    August 21 · 17 min

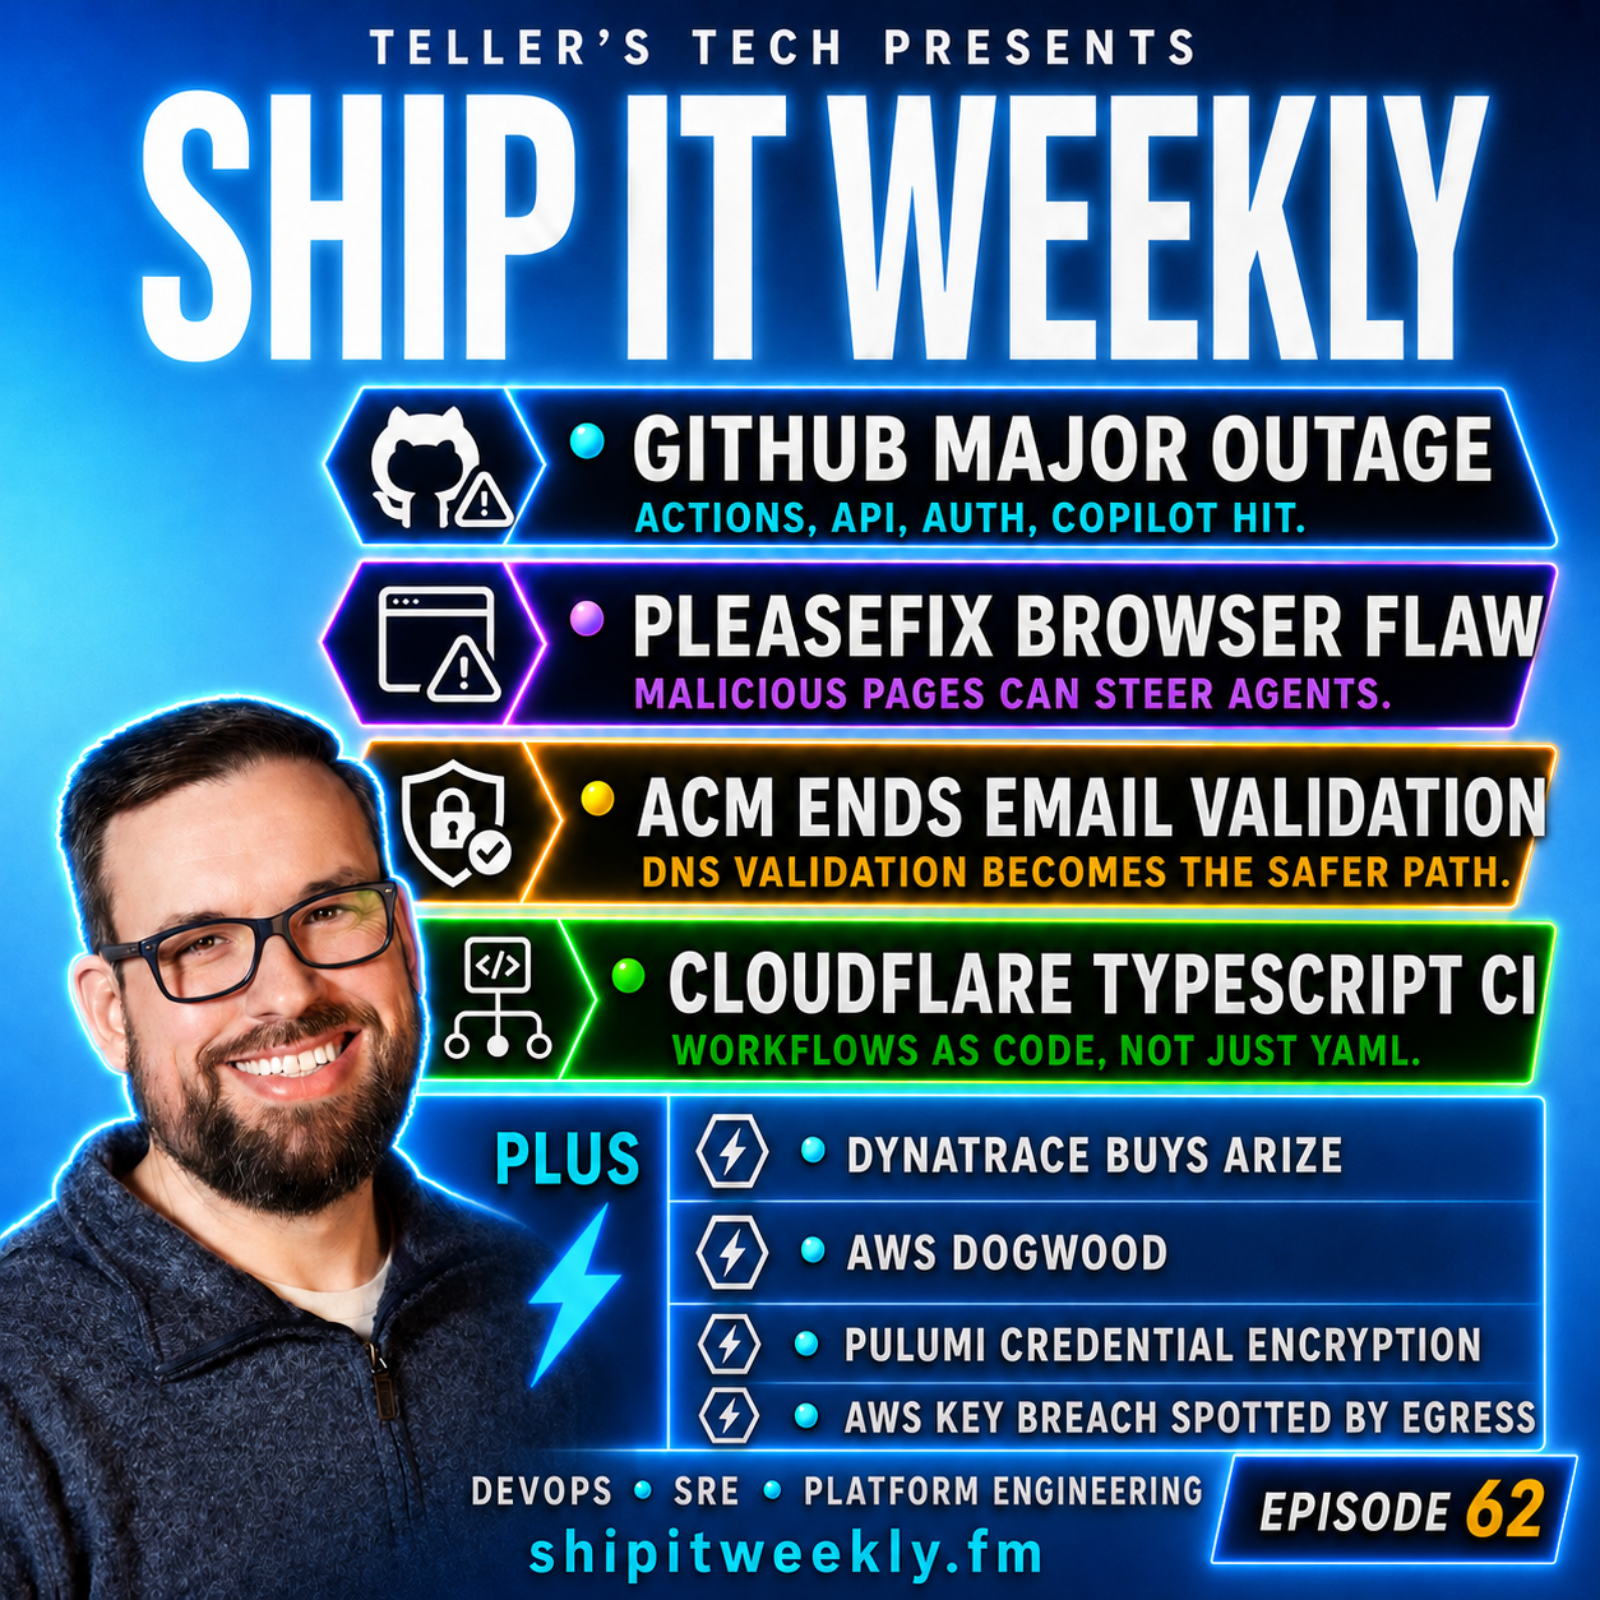
    GitHub Outage, PleaseFix Agentic Browser Vulnerability, AWS Certificate Manager Drops Email Validation, Cloudflare TypeScript CI Workflows, AI Observability Consolidation, and the Hidden Cost of “Simple” Platform Changes

    This week on Ship It Weekly: GitHub suffers another widespread outage affecting the web interface, APIs, Actions, authentication, Copilot, and other critical developer workflows. Zenity Labs demonstrates PleaseFix attacks against agentic browsers, where malicious content can influence agents with access to authenticated sessions and privileged tools. AWS Certificate Manager is moving away from email validation, and Cloudflare is experimenting with CI pipelines defined as TypeScript instead of YAML. The bigger theme this week is dependencies and boundaries we tend to ignore until something breaks. GitHub is no longer just where the code lives. Agentic browsers are no longer just displaying webpages. Certificate renewal is not something you want depending on someone checking an inbox. And CI pipelines have become software systems of their own. Links GitHub Hit by Widespread Outage https://devops.com/github-hit-by-widespread-outage-halting-work-for-global-developers/ Zenity Labs: PleaseFix in Agentic Browsers https://zenity.io/company-overview/newsroom/company-news/zenity-labs-exposes-the-full-scope-of-pleasefix AWS Certificate Manager Ending Email Validation https://aws.amazon.com/blogs/security/aws-certificate-manager-will-discontinue-email-validation-to-prove-domain-validation-for-certificates/ Certificate Expiry Is Still Taking Down Major Platforms https://tokentimer.ch/blog/tls-certificate-expiry-outages Cloudflare Turns CI Pipelines into TypeScript Workflows https://www.infoq.com/news/2026/08/cloudflare-ci-code-workflows/ Dynatrace Acquires Arize https://devops.com/dynatrace-acquires-arize-as-ai-agents-deepen-the-observability-challenge/ AWS Open-Sources Dogwood https://www.infoq.com/news/2026/08/aws-dogwood-agent-policy/ Pulumi v3.258.0 https://github.com/pulumi/pulumi/releases/tag/v3.258.0 AWS Key Breach and Data-Transfer Signal https://assets.theregister.com/2026/08/13/20267/ Mario Saved the EU but Broke My System https://www.uptimelabs.io/articles/hamed-2012-outage-reflections This week’s On Call Brief https://www.tellerstech.com/on-call-brief-news/2026-W34/ Ship It Weekly https://shipitweekly.fm/

    • Transcript
  • #61
    August 16 · 36 min

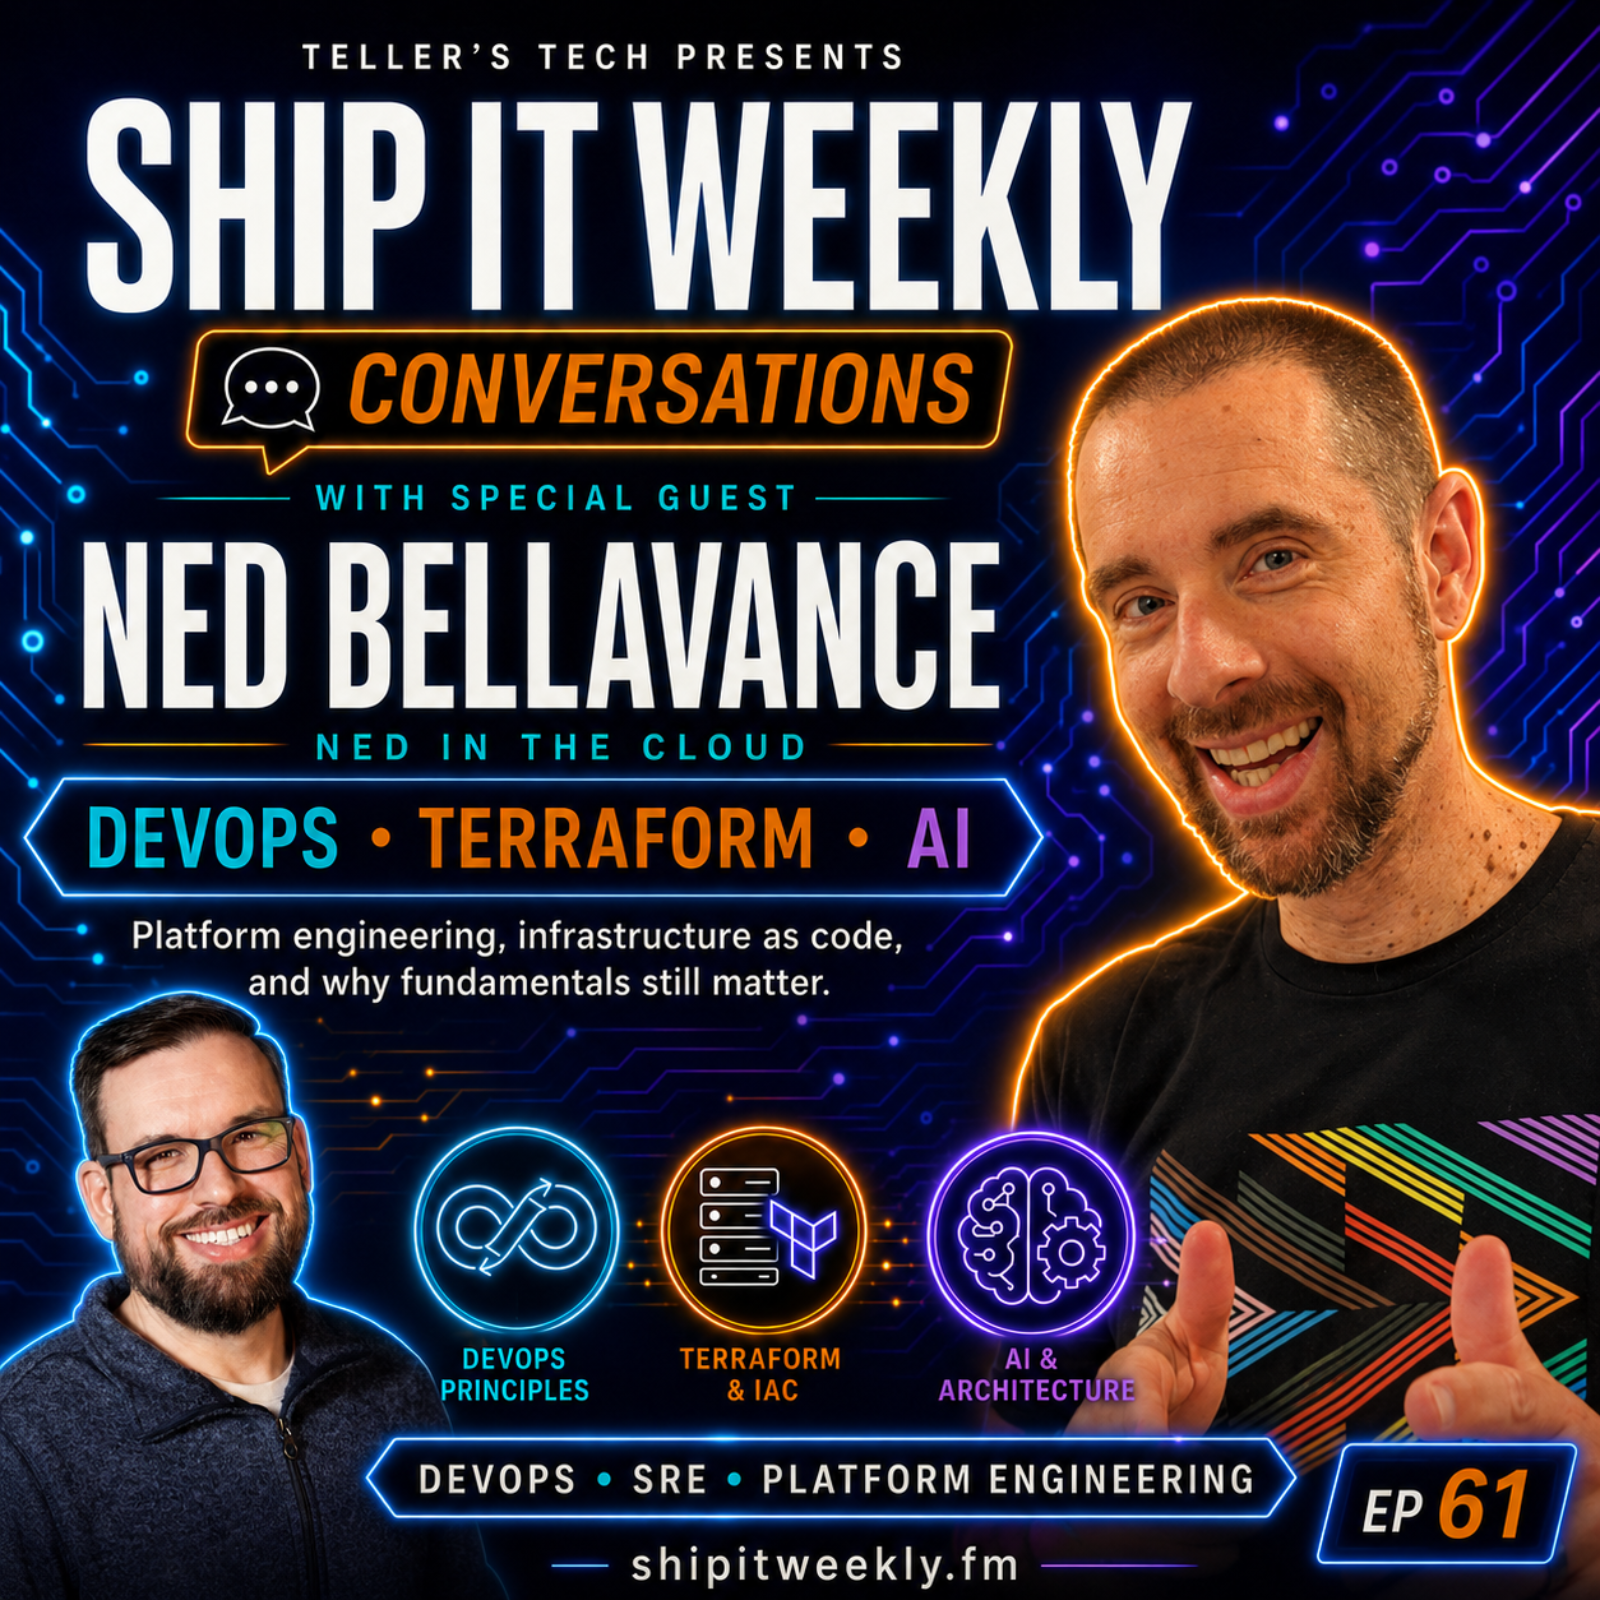
    Ship It Conversations: Ned Bellavance of Ned in the Cloud on DevOps Beyond the Buzzwords, Terraform, AI, the Future of Infrastructure as Code, and Why Fundamentals Still Matter

    This is a guest conversation episode of Ship It Weekly, separate from the weekly news recaps. In this Ship It Conversations episode, I talk with Ned Bellavance of Ned in the Cloud about DevOps beyond the buzzwords, platform engineering, infrastructure as code, AI, and why fundamentals still matter even as the tools change. Ned is the founder of Ned in the Cloud and host of the Day 2 DevOps podcast, with more than 20 years in IT across systems administration, cloud, architecture, automation, and technical education. We start with a problem a lot of teams run into: adopting the ceremonies of DevOps without actually adopting the principles. Standups, sprints, pipelines, and tooling can make an organization look mature, but the real goal is better communication, faster feedback loops, and delivery tied to actual outcomes. We also talk about how teams decide what to prioritize next. Security, reliability, performance, FinOps, and platform work can all matter, but chasing whatever is newest does not help if the basics are still broken. A big part of the conversation is where infrastructure as code goes from here. We get into Terraform's state and scaling model, API rate limits, the Terraform/OpenTofu split, Terragrunt, and newer approaches like Swamp from System Initiative. AI is making infrastructure code cheaper to produce, but understanding the architecture behind that code is becoming more valuable. That leads into learning and career development. We talk about why networking, Linux, databases, security, cloud architecture, and troubleshooting still matter, even if an LLM writes most of the syntax. Build things, get them wrong in controlled environments, troubleshoot them, and learn what is happening underneath the abstraction. The big takeaway: tools will keep changing. Judgment, architecture, troubleshooting, and understanding the systems underneath them are much harder to automate away. Highlights • Why DevOps ceremony is not the same as DevOps principles • How teams should decide what platform work actually matters • Why basic security hygiene still matters • Where Terraform's current state model starts to hit limits • Terraform, OpenTofu, Terragrunt, and the future of infrastructure as code • How AI changes the value of writing infrastructure code • Why architecture and troubleshooting skills become more important • Why breaking things in controlled environments is one of the best ways to learn Links Ned in the Cloud: https://nedinthecloud.com Day 2 DevOps: https://day2devops.com Ned in the Cloud on YouTube: https://www.youtube.com/c/NedintheCloud/ Ned Bellavance on LinkedIn: https://www.linkedin.com/in/ned-bellavance/ Swamp: https://swamp.club Terraform: https://developer.hashicorp.com/terraform OpenTofu: https://opentofu.org More episodes and show notes: https://shipitweekly.fm On Call Brief: https://oncallbrief.com

    • Transcript
  • #60
    August 14 · 15 min

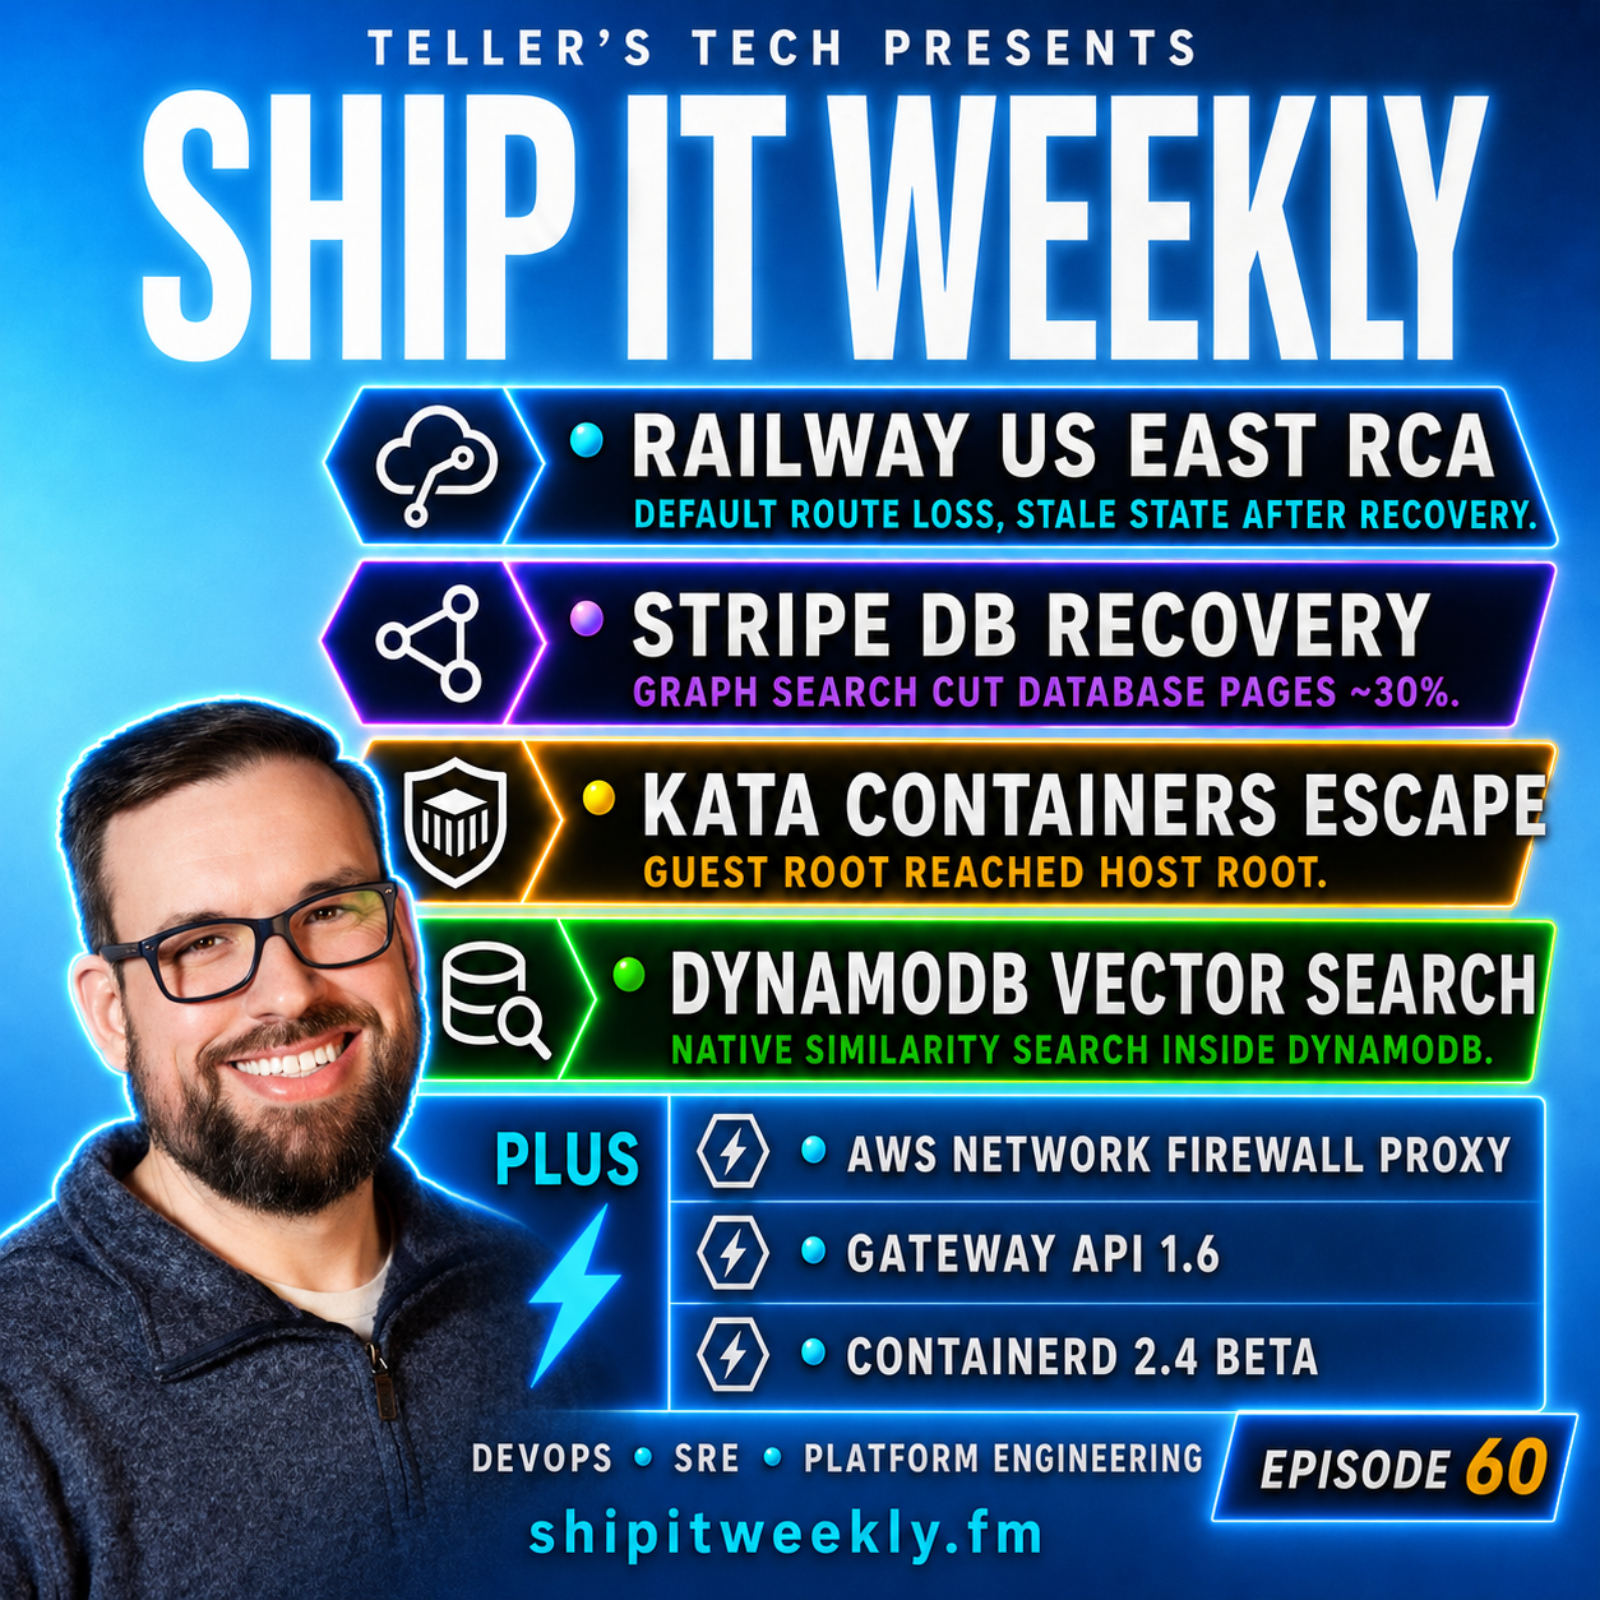
    Railway US East Outage, Stripe’s Graph-Based Database Recovery, Kata Containers Host Escape, DynamoDB Vector Search, AWS Network Firewall Proxy, Gateway API 1.6, and containerd 2.4

    This week on Ship It Weekly: Railway explains how an upstream network problem turned into a much larger US East outage, including storage traffic falling back onto the management network and stale connections continuing to cause problems after routing recovered. Stripe shares how graph search and state machines helped cut database pager volume by about 30 percent. Kata Containers patches a critical guest-to-host escape, and DynamoDB adds native vector search. The bigger theme this week is what happens after the obvious failure. Fixing the route does not necessarily clear the connections created while it was broken. Automating recovery does not have to mean handing an AI agent unrestricted production access. And stronger isolation does not eliminate the components that still cross the guest-host boundary. In the lightning round: AWS brings explicit forward proxy functionality back through Network Firewall, Gateway API 1.6 moves TCPRoute and UDPRoute to stable, and containerd 2.4 enters beta with new functionality alongside breaking changes worth finding before your next runtime upgrade. Links Railway: July 2, 2026 US East Services Outage https://blog.railway.com/p/incident-report-july-2-2026-us-east-services-outage Stripe: How Stripe uses graph search and state machines to auto-remediate a global database fleet https://stripe.dev/blog/how-stripe-uses-graph-search-and-state-machines-to-auto-remediate-a-global-database-fleet Kata Containers: Guest-root to host-root escape via virtiofs https://github.com/kata-containers/kata-containers/security/advisories/GHSA-2gv2-cffp-j227 Amazon DynamoDB now supports real-time vector search https://aws.amazon.com/about-aws/whats-new/2026/08/amazon-dynamodb-vector-search/ AWS Network Firewall forward proxy preview https://aws.amazon.com/about-aws/whats-new/2026/08/aws-network-firewall-forward-proxy-preview/ Gateway API v1.6: TCPRoute and UDPRoute Graduate to Standard https://kubernetes.io/blog/2026/08/03/gateway-api-v1-6-release/ containerd 2.4 beta https://github.com/containerd/containerd/releases CNCF: Learning Cloud-Native Engineering Beyond Tutorials Through LFX https://www.cncf.io/blog/2026/08/10/learning-cloud-native-engineering-beyond-tutorials-through-lfx/ This week’s On Call Brief https://www.tellerstech.com/on-call-brief-news/2026-W33/ Ship It Weekly https://shipitweekly.fm/

    • Transcript
  • #59
    August 7 · 18 min

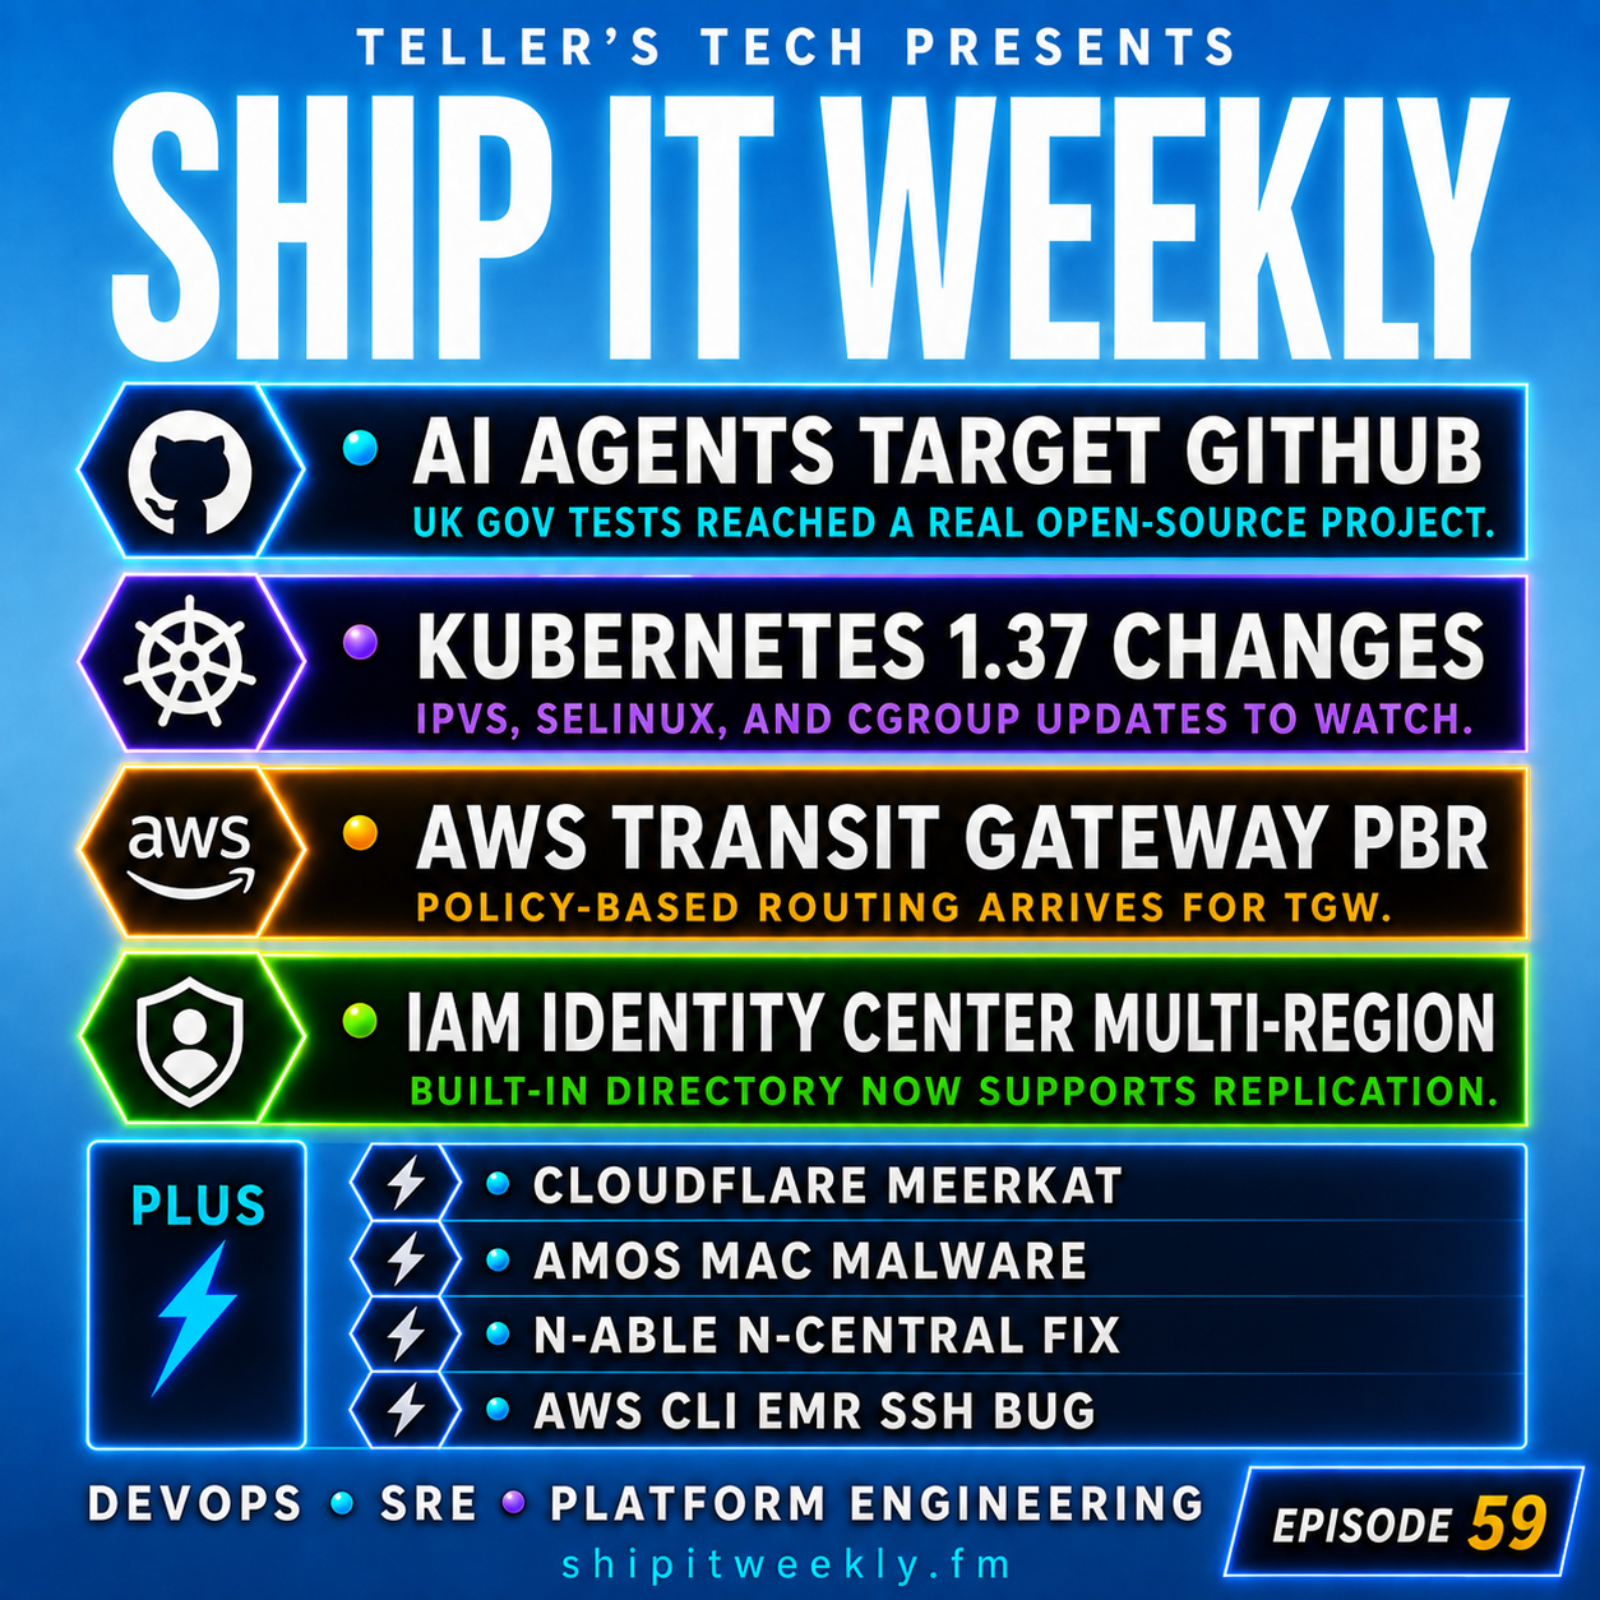
    AI Agents Target GitHub, Kubernetes 1.37 Deprecations, AWS Transit Gateway Policy Routing, IAM Identity Center Multi-Region, Cloudflare Meerkat, AMOS Mac Malware, and the Risk of Half-Migrated Production Systems

    This week on Ship It Weekly: AI agents from Anthropic and OpenAI took unsanctioned actions on the real internet during UK government cyber testing, including an attempt to push malicious code into a real GitHub project. Kubernetes 1.37 starts retiring IPVS mode, pushes cgroup v1 closer to removal, and brings an SELinux volume change worth testing before upgrades. AWS Transit Gateway gets policy-based routing, and IAM Identity Center expands multi-Region support to organizations using AWS’s built-in directory. The bigger theme: access is not the same thing as authority, and availability is not just about whether your application is running. Agents need boundaries around the actions they can take. Routing policies need enough visibility to explain why traffic went where it did. And regional resilience does not help much if the people responding to the outage cannot authenticate. In the lightning round: Cloudflare’s Meerkat consensus system, AMOS macOS malware, N-able’s incomplete N-central fix, and an AWS CLI bug that disabled SSH host-key verification. Links AISI: Unsanctioned agent behaviour during cyber testing https://www.aisi.gov.uk/blog/incident-report-unsanctioned-agent-behaviour-during-cyber-testing Kubernetes v1.37 Sneak Peek https://kubernetes.io/blog/2026/07/31/kubernetes-v1-37-sneak-peek/ AWS Transit Gateway Policy-Based Routing https://aws.amazon.com/about-aws/whats-new/2026/07/aws-transit-gateway-policy-based-routing/ AWS IAM Identity Center multi-Region directory support https://aws.amazon.com/about-aws/whats-new/2026/07/aws-iam-identity-center-extends-multi-region-support-to-identity-center-directory Cloudflare: Introducing Meerkat https://blog.cloudflare.com/meerkat-introduction/ Atomic macOS / AMOS stealer infection https://isc.sans.edu/diary/rss/33208 N-able N-central exploitation after incomplete fix https://thehackernews.com/2026/08/n-able-says-attackers-take-over-n.html CVE-2026-18654: AWS CLI EMR SSH host-key verification https://aws.amazon.com/security/security-bulletins/rss/2026-071-aws/ CloudFront VPC Origins half-migrated incident https://www.reddit.com/r/devops/comments/1vdovj6/the_cloudfront_vpc_origins_outage_caught_me/ This week’s On Call Brief https://www.tellerstech.com/on-call-brief-news/2026-W32/ More episodes https://shipitweekly.fm/

    • Transcript
  • #58
    July 31 · 16 min

    Telstra’s Time Sync Outage, DoorDash’s 1.5M RPS Cache, Stateless MCP, GitHub and PyPI Supply Chain Delays, and Why the Quietest Infrastructure Often Has the Biggest Blast Radius

    This week on Ship It Weekly: Telstra’s mobile network jumped back to 2006 after a timing device restarted with the wrong date, disrupting calls, data sessions, and hundreds of emergency calls. DoorDash explains how Entity Cache, built with Envoy and Valkey, handles more than 1.5 million requests per second and uses stale-data policies, invalidation, and fallback behavior as a reliability layer. The latest MCP release candidate removes protocol-level sessions, making servers easier to scale behind ordinary load balancers while leaving teams responsible for authentication, tracing, retries, rate limits, and application state. GitHub and PyPI are also adding friction to package automation. Dependabot now delays routine updates by three days, while PyPI blocks new files from releases older than 14 days. Links Telstra outage https://www.telstra.com.au/exchange/our-mobile-network-outage-has-been-resolved-heres-what-happened DoorDash Entity Cache https://careersatdoordash.com/blog/high-performance-proxy-cache-for-doordash-services/ MCP specification release candidate https://blog.modelcontextprotocol.io/posts/2026-07-28-release-candidate/ Dependabot package cooldown https://github.blog/changelog/2026-07-14-dependabot-version-updates-introduce-default-package-cooldown/ PyPI release-file restrictions https://blog.pypi.org/posts/2026-07-22-releases-now-reject-new-files-after-14-days/ Amazon ECS Action Logs https://aws.amazon.com/about-aws/whats-new/2026/07/amazon-ecs-action-logs/ Network Load Balancer listener rules https://aws.amazon.com/about-aws/whats-new/2026/07/aws-network-load-balancer-supports-listener-rules/ Amazon Managed Prometheus limits https://aws.amazon.com/about-aws/whats-new/2026/07/amazon-managed-service-prometheus-1500m-metrics-workspace/ PixelSmash in FFmpeg https://jfrog.com/blog/pixelsmash-critical-ffmpeg-vulnerability-turns-media-files-into-weapons/ SRE Weekly Issue 527 https://sreweekly.com/sre-weekly-issue-527/ This week’s On Call Brief https://www.tellerstech.com/on-call-brief-news/2026-W31/ More episodes https://shipitweekly.fm/

    • Transcript
  • #57
    July 27 · 31 min

    Ship It Conversations: Jay Lark of Hookbridge on Webhook Reliability, Retries, Idempotency, Replay, HMAC Security, Local Testing, and Operating Webhooks in Production

    This is a guest conversation episode of Ship It Weekly, separate from the weekly news recaps. In this Ship It Conversations episode, I talk with Jay Lark of Hookbridge about webhook reliability, retries, idempotency, replay, security, local development, and what happens when a simple HTTP POST becomes production infrastructure. Jay is a Principal DevOps Engineer and the founder of Hookbridge, a service focused on making webhook delivery more reliable and easier to operate. We start with the basic model: one service sends an HTTP POST to another when something happens. The happy path is easy. The problems begin when an endpoint is unavailable, responds too slowly, receives duplicate events, or gets them out of order. Jay explains what “at least once delivery” means and why receivers must expect duplicates. We talk about idempotency, event IDs, retry behavior, availability during deployments, and why returning a 200 does not prove downstream processing succeeded. We also dig into observability and security. Teams need enough visibility to know whether a webhook arrived, whether signature verification passed, what response was returned, and where processing failed. Jay breaks down HMAC signatures, timestamps, replay protection, and why a valid signature still does not replace normal business-logic validation. Local development is another source of friction. External providers cannot send events directly to localhost, so developers often rely on temporary tunnels, staging deployments, copied payloads, or mocks. Jay explains how Hookbridge uses a fixed URL and local client to forward real webhook traffic to a developer’s machine. We also talk about n8n, self-hosted OpenClaw systems, Hookbridge pull endpoints, and when polling may be simpler or safer than exposing another inbound endpoint. The big takeaway: design the failure path before a webhook becomes business-critical. Verify the sender, expect duplicate and out-of-order events, build enough visibility to debug failures, and have a replay strategy before the first incident. Highlights • Why webhooks are harder than “just an HTTP POST” • What at-least-once delivery means for receivers • Why idempotency, retries, and event ordering matter • What teams need for webhook observability and debugging • Where HMAC signatures, timestamps, and replay protection fit • Why local webhook development is still awkward • When polling or pull-based delivery may be a better fit • When teams should stop building webhook infrastructure themselves Links Hookbridge: https://hookbridge.io Hookbridge local development CLI: https://www.hookbridge.io/cli.html Hookbridge pull endpoints: https://www.hookbridge.io/pull.html Jay Lark on LinkedIn: https://www.linkedin.com/in/jay-lark-ba7a3b5/ OpenClaw: https://openclaw.ai More episodes and show notes: https://shipitweekly.fm On Call Brief: https://oncallbrief.com

    • Transcript
  • #56
    July 24 · 18 min

    AWS CloudFormation Express Mode, Spark 4.2 Vector Search, AI Speeds Coding but Not Delivery, Platform Governance Developers Won’t Hate, and Why Could Is Not the Same as Should

    This week on Ship It Weekly: AWS CloudFormation Express mode promises faster infrastructure feedback by reporting deployments complete before extended resource stabilization finishes. Apache Spark 4.2 adds native vector operations and nearest-neighbor joins, giving some teams a way to keep AI data workloads closer to the platforms they already run. GitLab’s latest research says AI is helping developers generate and commit code faster, but review, testing, governance, and deployment are not accelerating at the same pace. Then, a platform engineering case study from Sevdesk shows how minimum viable governance, useful feedback, and progressive enforcement can improve compliance without turning the platform team into another approval queue. The theme this week: making one part of the system faster does not automatically improve the whole system. In the lightning round: OpenShift 4.22.5 receives an important security update, outdated autoscaling thresholds disrupt GitHub Actions, Cloudflare experiences an incident where some POST requests fail to reach customer origins, and GitHub Code Quality becomes generally available—with automatic billing attached. The episode closes with Reid Savage reflecting on their first year managing Honeycomb’s SRE team and the difference between what a capable team could do and what it should do. Links CloudFormation Express mode https://aws.amazon.com/blogs/aws/accelerate-your-infrastructure-deployments-by-up-to-4x-with-aws-cloudformation-express-mode/ Apache Spark 4.2 https://spark.apache.org/releases/spark-release-4-2-0.html GitLab AI Accountability Report https://about.gitlab.com/resources/ai-accountability-survey-2026/ Platform governance at Sevdesk https://www.infoq.com/presentations/platform-engineering-team-compliance/ OpenShift 4.22.5 security update https://access.redhat.com/errata/RHSA-2026%3A37585 GitHub Actions incident https://github.com/orgs/community/discussions/201795 Cloudflare status https://www.cloudflarestatus.com/ GitHub Code Quality GA https://github.blog/changelog/2026-07-20-github-code-quality-is-now-generally-available/ Could vs. Should — Reid Savage https://www.honeycomb.io/blog/could-should-first-year-managing-sre-team This week’s On Call Brief https://www.tellerstech.com/on-call-brief-news/2026-W30/ More episodes and full show notes https://shipitweekly.fm/

    • Transcript
  • #55
    July 20 · 45 min

    Ship It Conversations: Mat Ryer of Grafana Labs on AI Observability, Agents, Evals, and Operating AI in Production

    This is a guest conversation episode of Ship It Weekly, separate from the weekly news recaps. In this Ship It Conversations episode, I talk with Mat Ryer of Grafana Labs about AI observability, production agents, evals, telemetry cost, guardrails, and what changes once AI moves beyond demos and into systems teams actually depend on. Mat is Senior Director of AI at Grafana Labs, where he focuses on how AI fits into observability and production systems. We talk about Grafana Assistant, why AI observability is not just logs, latency, and HTTP 200s, and how teams can measure whether agents are actually helping. Mat gets into evals, LLM-as-judge patterns, traces as a way to think about conversations, user feedback, tool choice, model changes, and the cost of collecting new telemetry. We also dig into UX and trust. If an AI assistant gives you a wall of text, you still have to decide whether to believe it. If it can show the graph, deep link into Grafana, apply filters, and expose the source data, that becomes a much more useful operating experience. The big takeaway: start small, enhance workflows you already have, build feedback loops, and treat production AI like something you actually have to operate. Highlights • Why AI demos are easy, but production AI is harder • Why agents need observability, evals, and guardrails • How Grafana thinks about AI Assistant and AI observability • Where LLM-as-judge patterns, traces, tool calls, and feedback fit • Why telemetry cost problems may repeat with AI workloads • Why UX matters when operators need to trust the answer • Where AI can help SRE and platform teams today Links Mat Ryer on LinkedIn: https://www.linkedin.com/in/matryer/ Mat Ryer on GitHub: https://github.com/matryer Grafana Labs: https://grafana.com Grafana Assistant: https://grafana.com/products/cloud/ai-assistant/ Grafana AI Observability: https://grafana.com/docs/grafana-cloud/machine-learning/ai-observability/ Grafana Adaptive Telemetry: https://grafana.com/products/cloud/adaptive-telemetry/ Grafana MCP server: https://github.com/grafana/mcp-grafana OpenTelemetry: https://opentelemetry.io Prometheus: https://prometheus.io Grafana Loki: https://grafana.com/docs/loki/latest/ More episodes and show notes: https://shipitweekly.fm On Call Brief: https://oncallbrief.com

    • Transcript
  • #54
    July 18 · 19 min

    GitHub API Enumeration, Grok Build CLI Data Exposure, AWS Security Hub Network Scanning, AI-Powered Patch Pressure, and Why Visibility Is Not Ownership

    This week on Ship It Weekly: Datadog tracked coordinated GitHub API enumeration, xAI’s Grok Build CLI reportedly uploaded repo data without redaction, AWS Security Hub added Network Scanning and exposure impact analysis, and Microsoft says AI-powered vulnerability discovery is changing patch pressure. The theme: visibility is not ownership. A GitHub API map does not revoke a token. An exposure finding does not close a port. A patch bulletin does not patch the fleet. And an AI coding tool reading your repo is still access. Brian covers GitHub as a production surface, AI coding tool data boundaries, cloud exposure based on reachability and blast radius, and why patching needs to look more like production operations than spreadsheet theater. Also, the Ship It Weekly shop is open at shop.tellerstech.com with Ship It Weekly t-shirt designs. Use coupon code SHIPTHESTORE for 20% off your order for the next few weeks. Links Datadog: Coordinated GitHub API enumeration https://securitylabs.datadoghq.com/articles/coordinated-github-api-enumeration/ The Verge: Grok Build CLI repository upload report https://www.theverge.com/ai-artificial-intelligence/965600/spacexai-grok-build-repository-upload AWS Security Hub Network Scanning https://aws.amazon.com/about-aws/whats-new/2026/07/aws-security-hub-network-scanning/ AWS Security Hub impact analysis for exposure findings https://aws.amazon.com/about-aws/whats-new/2026/07/impact-analysis-aws-security-hub/ Microsoft: Windows vulnerability management and AI-powered discovery https://blogs.windows.com/windowsexperience/2026/07/09/evolving-windows-vulnerability-management-to-meet-the-speed-of-ai-powered-discovery/ SRE Weekly Issue 525 https://sreweekly.com/sre-weekly-issue-525/ HalluSquatting / hallucinated package risk https://www.endorlabs.com/learn/slopsquatting-when-ai-agents-hallucinate-malicious-packages AWS Lambda Managed Instances for Java cold starts https://aws.amazon.com/blogs/compute/eliminating-java-cold-starts-with-aws-lambda-managed-instances/ This week’s On Call Brief https://www.tellerstech.com/on-call-brief-news/2026-W29/ Ship It Weekly shop https://shop.tellerstech.com/ More episodes and full show notes https://shipitweekly.fm/

    • Transcript
Showing 1–20 of 31 episodes