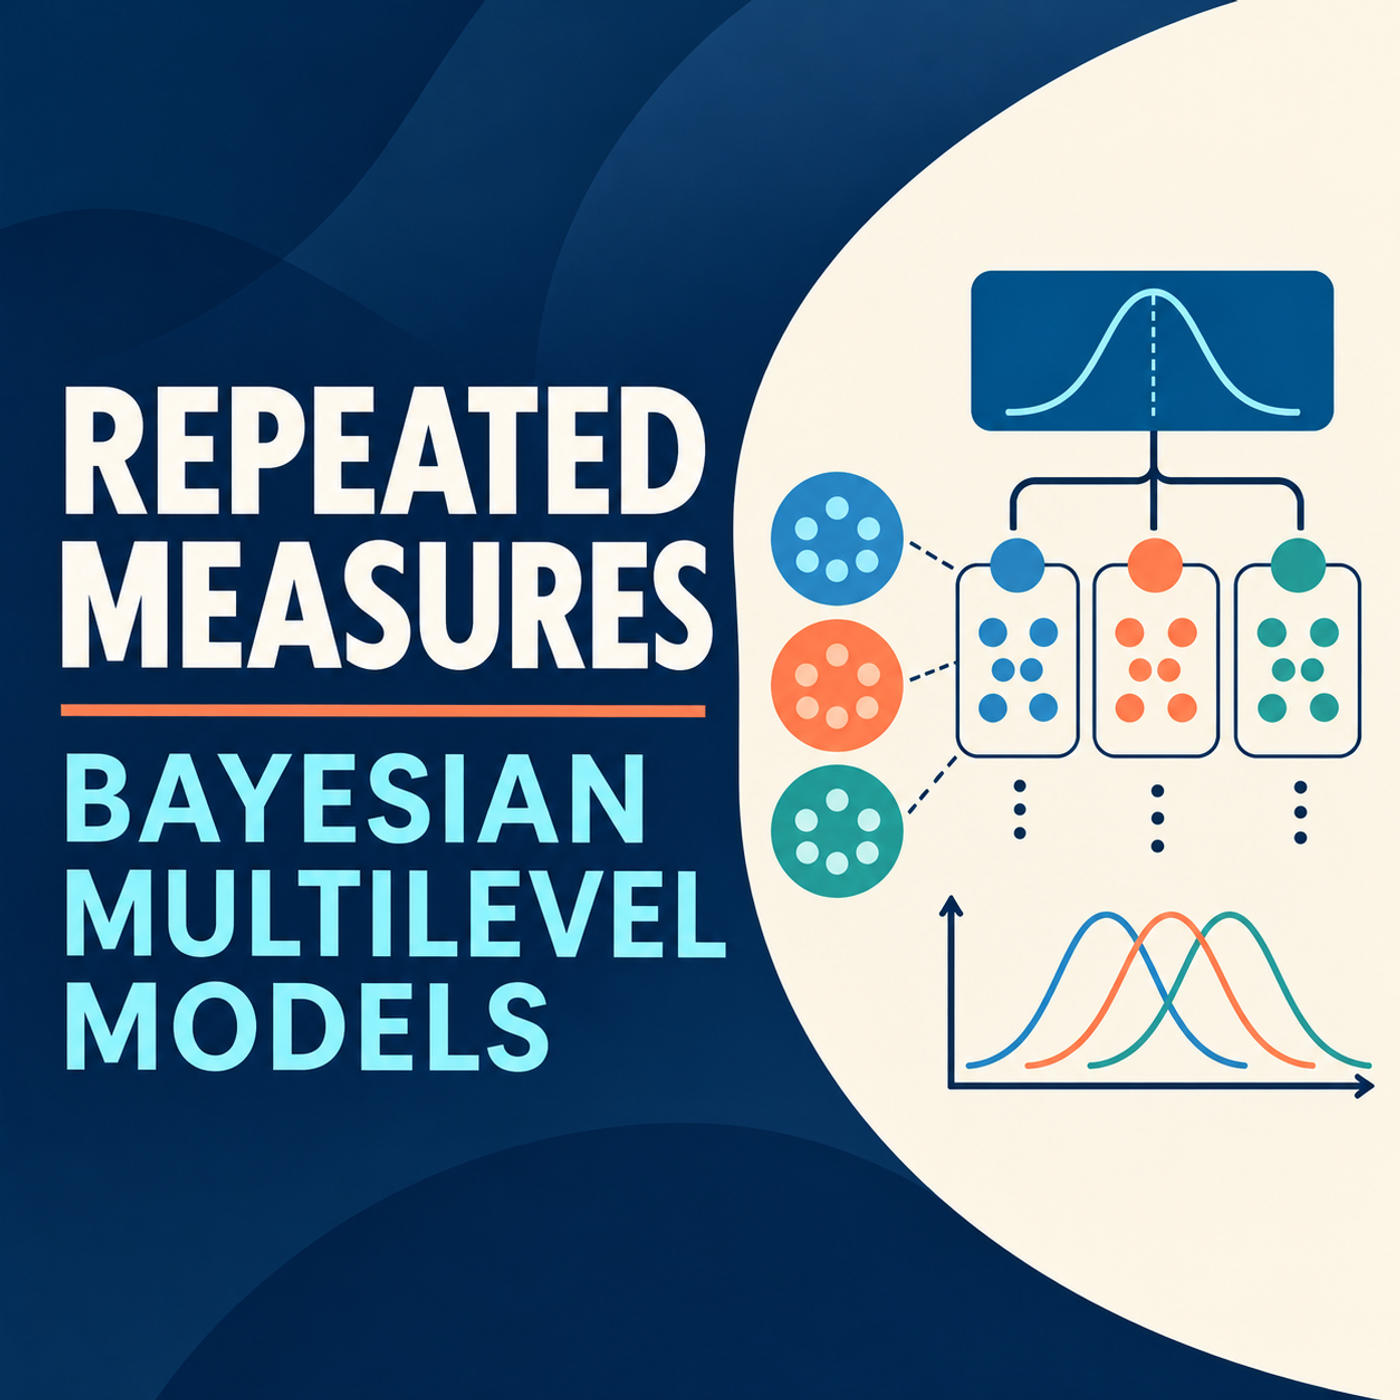
Why Start with Bayesian Multilevel Models for Repeated Measures?
transcript
show notes
Today's clip is from Episode 168 of Learning Bayesian Statistics, featuring Santiago Barreda, who joins host Alex Andorra to discuss Bayesian multilevel models and why they are particularly useful for researchers working with repeated measures data.
Santiago explains why he believes students in linguistics and related fields should spend less time learning traditional statistical models like t-tests and ANOVAs, and start directly with the multilevel models they will actually use in their research. In fields like linguistics, researchers often collect hundreds of observations from each listener, making repeated measures data the norm rather than the exception.
He also discusses the motivation behind his book, *Bayesian Multilevel Models for Repeated Measures Data*, which aims to make these methods more accessible through fully worked examples. The book walks readers through research questions, model structure, interpretation, visualisation and reporting results, with comparisons to equivalent frequentist analyses.
Full discussion here
Support & Resources
→ Support the show on Patreon
→ Bayesian Modeling Course (first 2 lessons free):
Our theme music is « Good Bayesian », by Baba Brinkman (feat MC Lars and Mega Ran). Check out his awesome work!