CyberCode Academy · August 2 · 19 min
Course 40 - Web Scraping with Python | Episode 22: Mastering Tree Traversal, CSS Selectors, and XPath
0:00-19:25
transcript
show notes
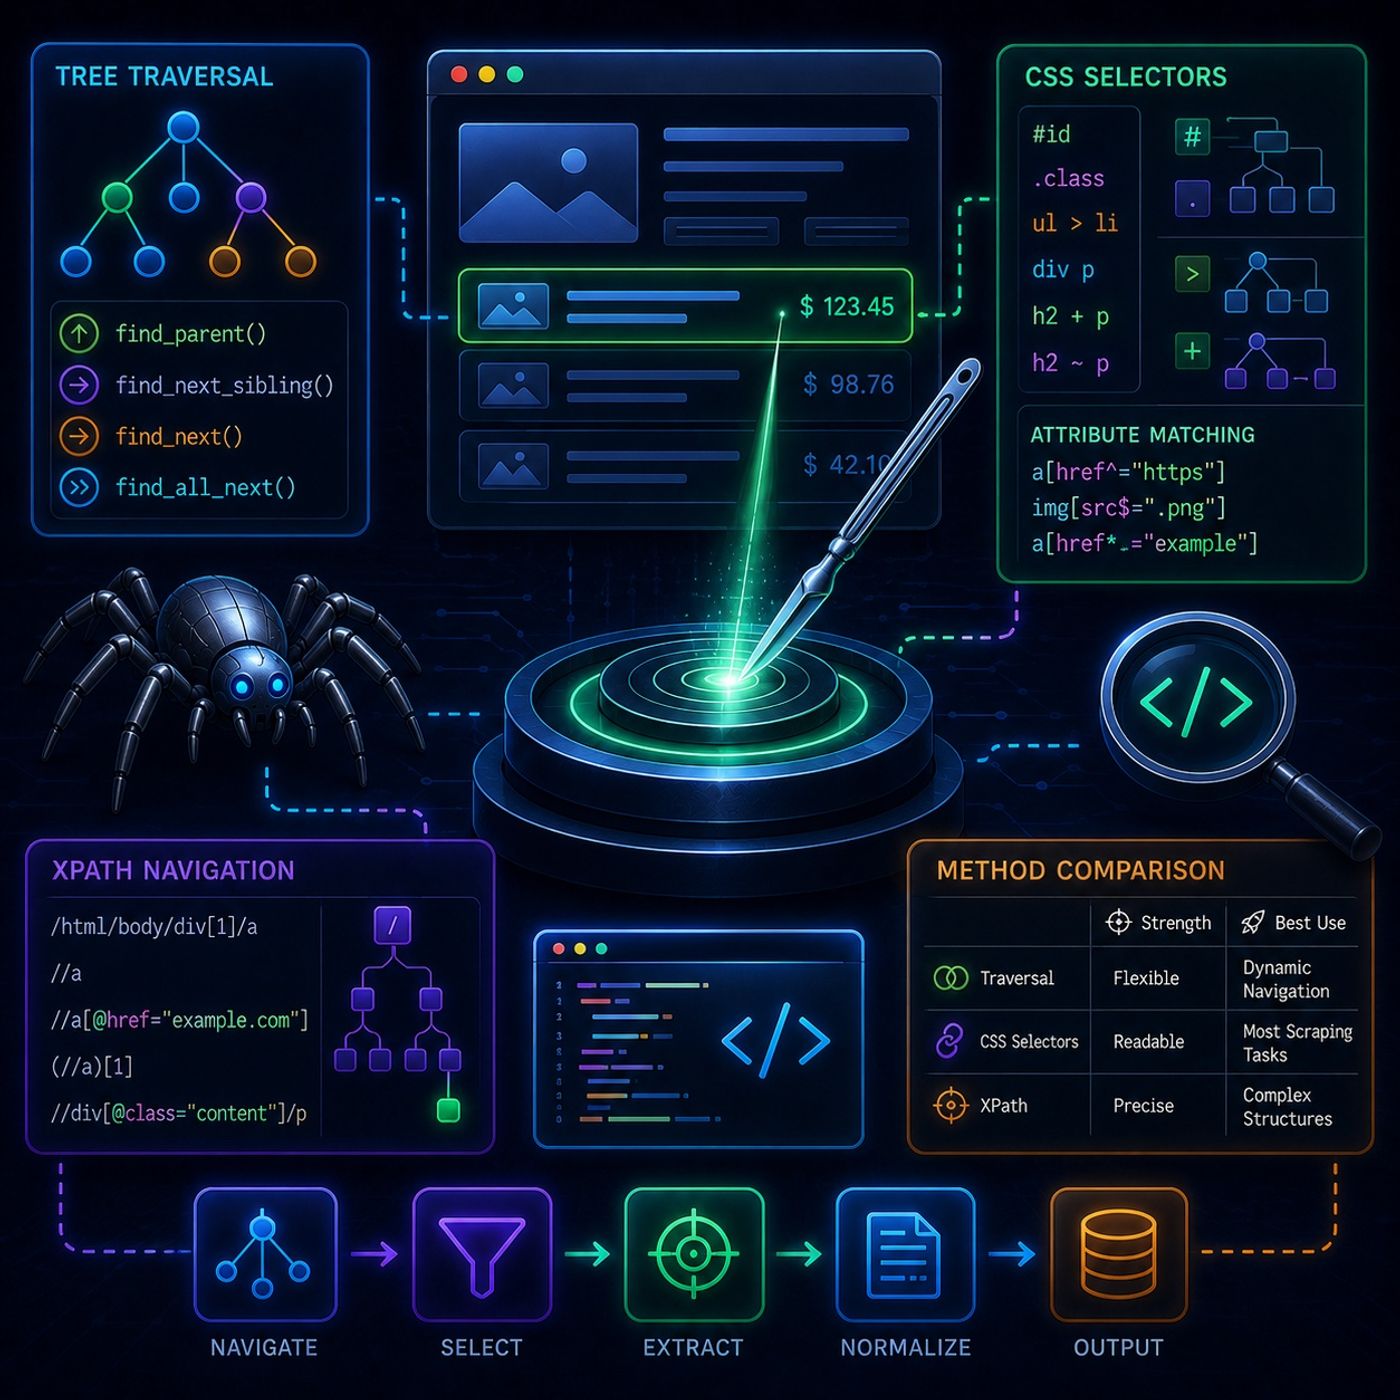
In this lesson, you’ll learn about: precision data extraction using advanced tree traversal, powerful CSS selectors, and XPath navigation for handling even the most complex web structures1. Advanced Tree Traversal (Beyond Basics)🔹 Navigating the HTML “Family Tree”Instead of just searching, you move through the structure intelligently.🔹 Key Navigation Methodstag.find_parent() tag.find_next_sibling() tag.find_next() tag.find_all_next() 🔹 What Each Does
Traversal lets you start anywhere and still reach your target2. CSS Selectors (Soup Sieve Power)🔹 Modern, Flexible SelectionBeautiful Soup supports CSS selectors via Soup Sieve.🔹 Basic Syntaxsoup.select("div.classname") soup.select("#main") soup.select("ul > li") 🔹 Selector Types
CSS selectors are often cleaner and more readable than manual navigation3. Attribute Matching in CSS🔹 Targeting Dynamic Datasoup.select('a[href^="https"]') soup.select('img[src$=".png"]') soup.select('a[href*="example"]') 🔹 Matching Types
Perfect for scraping dynamic or partially known values4. XPath Navigation (Precision Mode)🔹 Path-Based TargetingXPath works like navigating folders:🔹 Examples# Absolute path /html/body/div[1]/a # Global search //a # Attribute filtering //a[@href="example.com"] # Indexing (//a)[1] 🔹 Key Features
XPath is the most precise but strict method5. CSS vs XPath vs TraversalMethodStrengthBest UseTraversalFlexibleDynamic navigationCSS SelectorsReadableMost scraping tasksXPathPreciseComplex structures6. Combining Techniques🔹 Real Power Comes from MixingExample workflow:
No single method is enough for all cases7. Mental ModelThink like this:
You can listen and download our episodes for free on more than 10 different platforms:
https://linktr.ee/cybercode_academy
- find_parent() → move upward
- find_next_sibling() → next element at same level
- find_next() → next matching element anywhere after
- find_all_next() → all matches after current point
Traversal lets you start anywhere and still reach your target2. CSS Selectors (Soup Sieve Power)🔹 Modern, Flexible SelectionBeautiful Soup supports CSS selectors via Soup Sieve.🔹 Basic Syntaxsoup.select("div.classname") soup.select("#main") soup.select("ul > li") 🔹 Selector Types
- #id → specific element
- .class → group of elements
- A > B → direct children only
- A B → any nested descendants
CSS selectors are often cleaner and more readable than manual navigation3. Attribute Matching in CSS🔹 Targeting Dynamic Datasoup.select('a[href^="https"]') soup.select('img[src$=".png"]') soup.select('a[href*="example"]') 🔹 Matching Types
- ^= → starts with
- $= → ends with
- *= → contains
Perfect for scraping dynamic or partially known values4. XPath Navigation (Precision Mode)🔹 Path-Based TargetingXPath works like navigating folders:🔹 Examples# Absolute path /html/body/div[1]/a # Global search //a # Attribute filtering //a[@href="example.com"] # Indexing (//a)[1] 🔹 Key Features
- Navigate from root or anywhere
- Filter by attributes
- Select exact index
XPath is the most precise but strict method5. CSS vs XPath vs TraversalMethodStrengthBest UseTraversalFlexibleDynamic navigationCSS SelectorsReadableMost scraping tasksXPathPreciseComplex structures6. Combining Techniques🔹 Real Power Comes from MixingExample workflow:
- Start with CSS selector
- Navigate with traversal
- Refine with XPath
No single method is enough for all cases7. Mental ModelThink like this:
- 🧭 Traversal → move through structure
- 🎯 CSS → quickly target patterns
- 🔬 XPath → pinpoint exact elements
- Navigating directly to it
- Selecting it with intent
- Extracting it efficiently
You can listen and download our episodes for free on more than 10 different platforms:
https://linktr.ee/cybercode_academy
links1