CyberCode Academy · July 29 · 22 min
Course 40 - Web Scraping with Python | Episode 19: Tree Navigation, Advanced Filtering, and Link Extraction
0:00-22:37
transcript
show notes
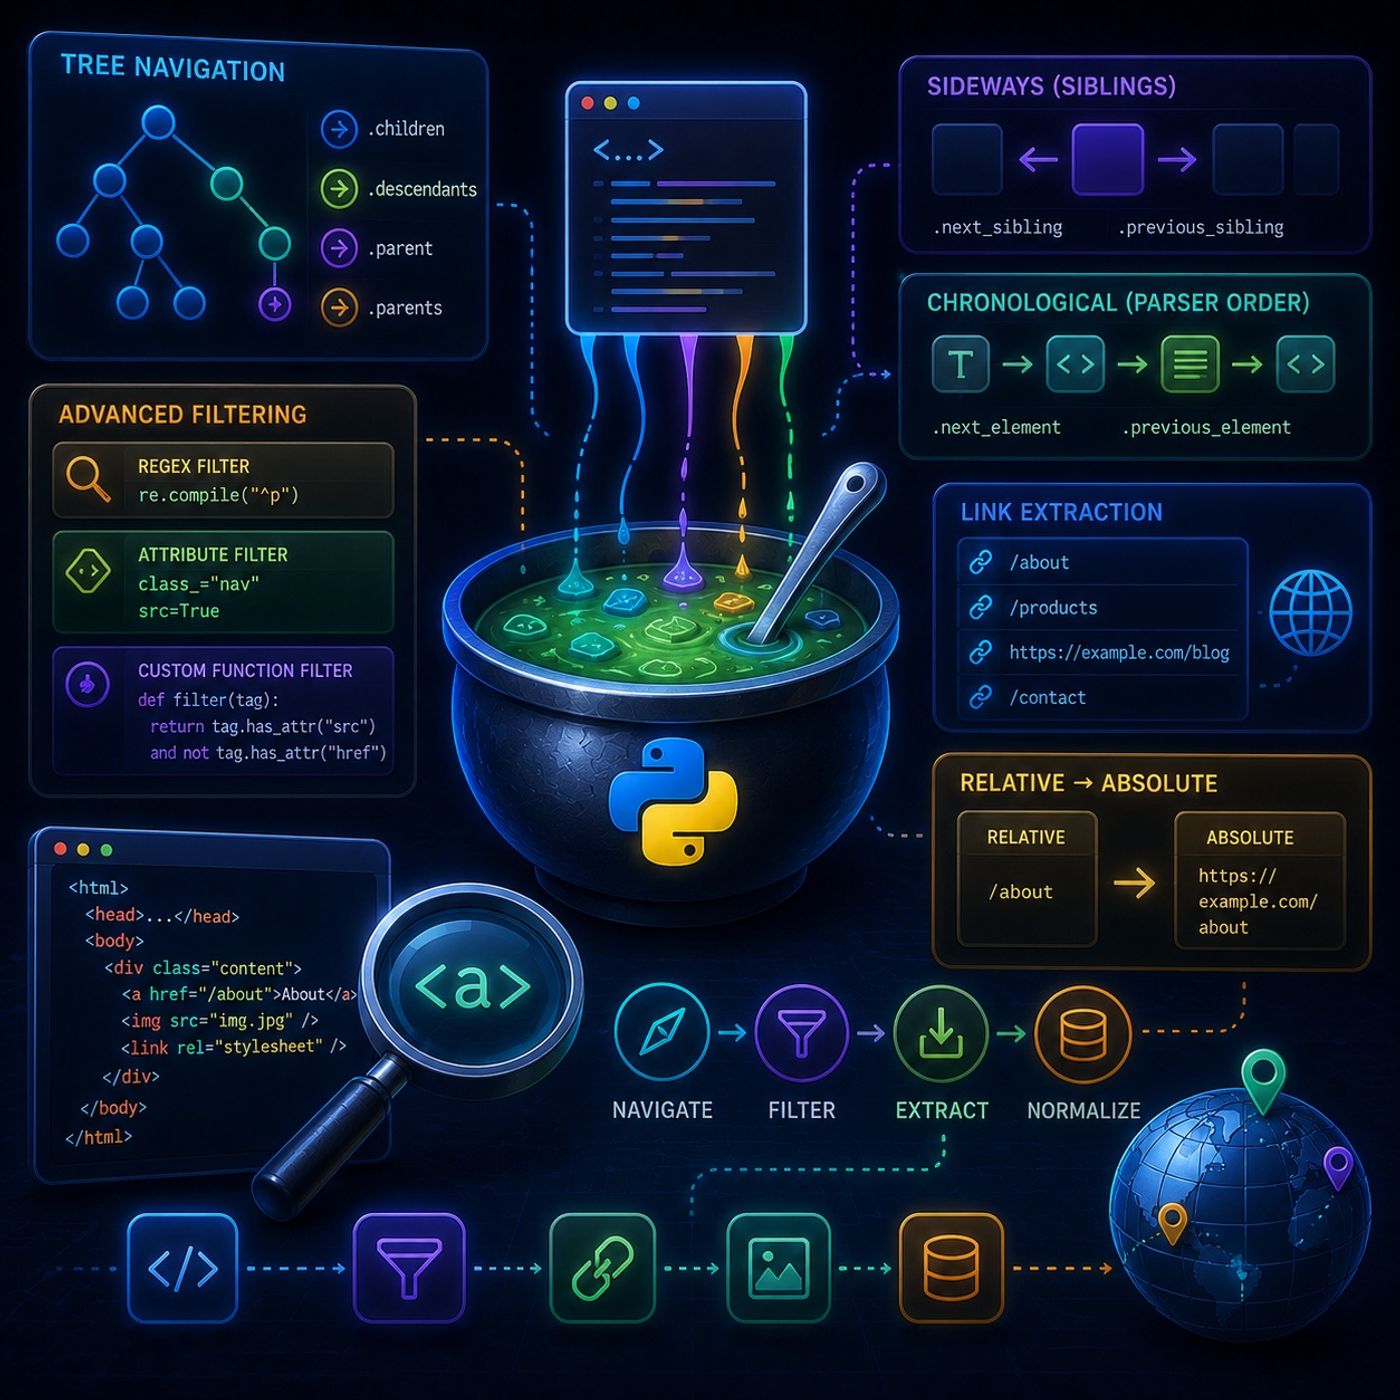
In this lesson, you’ll learn about: advanced Beautiful Soup navigation, powerful filtering techniques, and how to extract and normalize real-world data like links from complex websites1. Advanced Tree Navigation🔹 Multi-Directional MovementBeautiful Soup allows you to move through HTML in three different dimensions:🔹 Vertical Navigationlist(tag.children) list(tag.descendants) tag.parent tag.parents
.children is shallow — .descendants is deep traversal🔹 Sideways Navigation (Siblings)tag.next_sibling tag.previous_sibling
next_element ≠ next_sibling
It follows document order, not hierarchy2. Advanced Filtering Techniques🔹 Precision Data Targeting3. Filtering with Regular Expressionsimport re soup.find_all(re.compile("^p"))
You can filter by value OR existence of attributes5. Custom Function Filters (Power Feature)def has_src_no_href(tag): return tag.has_attr("src") and not tag.has_attr("href") soup.find_all(has_src_no_href) 👉 Key Insight
Custom functions = unlimited filtering logic6. Real-World Example: Link Extraction🔹 Extracting Links from a Page🔹 Extract All Linkslinks = soup.find_all("a") for link in links: print(link.get("href")) 7. Relative vs Absolute URLsTypeExampleRelative/aboutAbsolutehttps://site.com/about🔹 Convert to Absolutebase = "https://example.com" full_url = base + relative_url 👉 Key Insight
Most websites use relative links → you must normalize them8. Extracting All Resource Links# Anchor links soup.find_all("a") # Stylesheets / metadata soup.find_all("link") # Images soup.find_all("img") 👉 Key Insight
Data isn’t only in tags — it's everywhere9. Mental ModelThink of advanced scraping as:
You can listen and download our episodes for free on more than 10 different platforms:
https://linktr.ee/cybercode_academy
- .children → direct children only
- .descendants → all nested elements
- .parent / .parents → move upward
.children is shallow — .descendants is deep traversal🔹 Sideways Navigation (Siblings)tag.next_sibling tag.previous_sibling
- Moves across elements at the same level
- Follows actual parsing sequence
- Can move into text, nested tags, or out of structure
next_element ≠ next_sibling
It follows document order, not hierarchy2. Advanced Filtering Techniques🔹 Precision Data Targeting3. Filtering with Regular Expressionsimport re soup.find_all(re.compile("^p"))
- Matches tags starting with "p"
- Useful for pattern-based selection
- class_ → avoids Python keyword conflict
- src=True → finds elements that have the attribute
You can filter by value OR existence of attributes5. Custom Function Filters (Power Feature)def has_src_no_href(tag): return tag.has_attr("src") and not tag.has_attr("href") soup.find_all(has_src_no_href) 👉 Key Insight
Custom functions = unlimited filtering logic6. Real-World Example: Link Extraction🔹 Extracting Links from a Page🔹 Extract All Linkslinks = soup.find_all("a") for link in links: print(link.get("href")) 7. Relative vs Absolute URLsTypeExampleRelative/aboutAbsolutehttps://site.com/about🔹 Convert to Absolutebase = "https://example.com" full_url = base + relative_url 👉 Key Insight
Most websites use relative links → you must normalize them8. Extracting All Resource Links# Anchor links soup.find_all("a") # Stylesheets / metadata soup.find_all("link") # Images soup.find_all("img") 👉 Key Insight
Data isn’t only in tags — it's everywhere9. Mental ModelThink of advanced scraping as:
- 🧭 Navigation → move through tree
- 🎯 Filtering → select exactly what you want
- 🔗 Extraction → collect and normalize data
- Deep traversal (descendants, parents)
- Smart filtering (regex + functions)
- Real-world normalization (links, resources)
You can listen and download our episodes for free on more than 10 different platforms:
https://linktr.ee/cybercode_academy
links1